Why Evaluations Matter
Evaluations transform ad-hoc testing into systematic quality assurance:Evaluation Dashboard
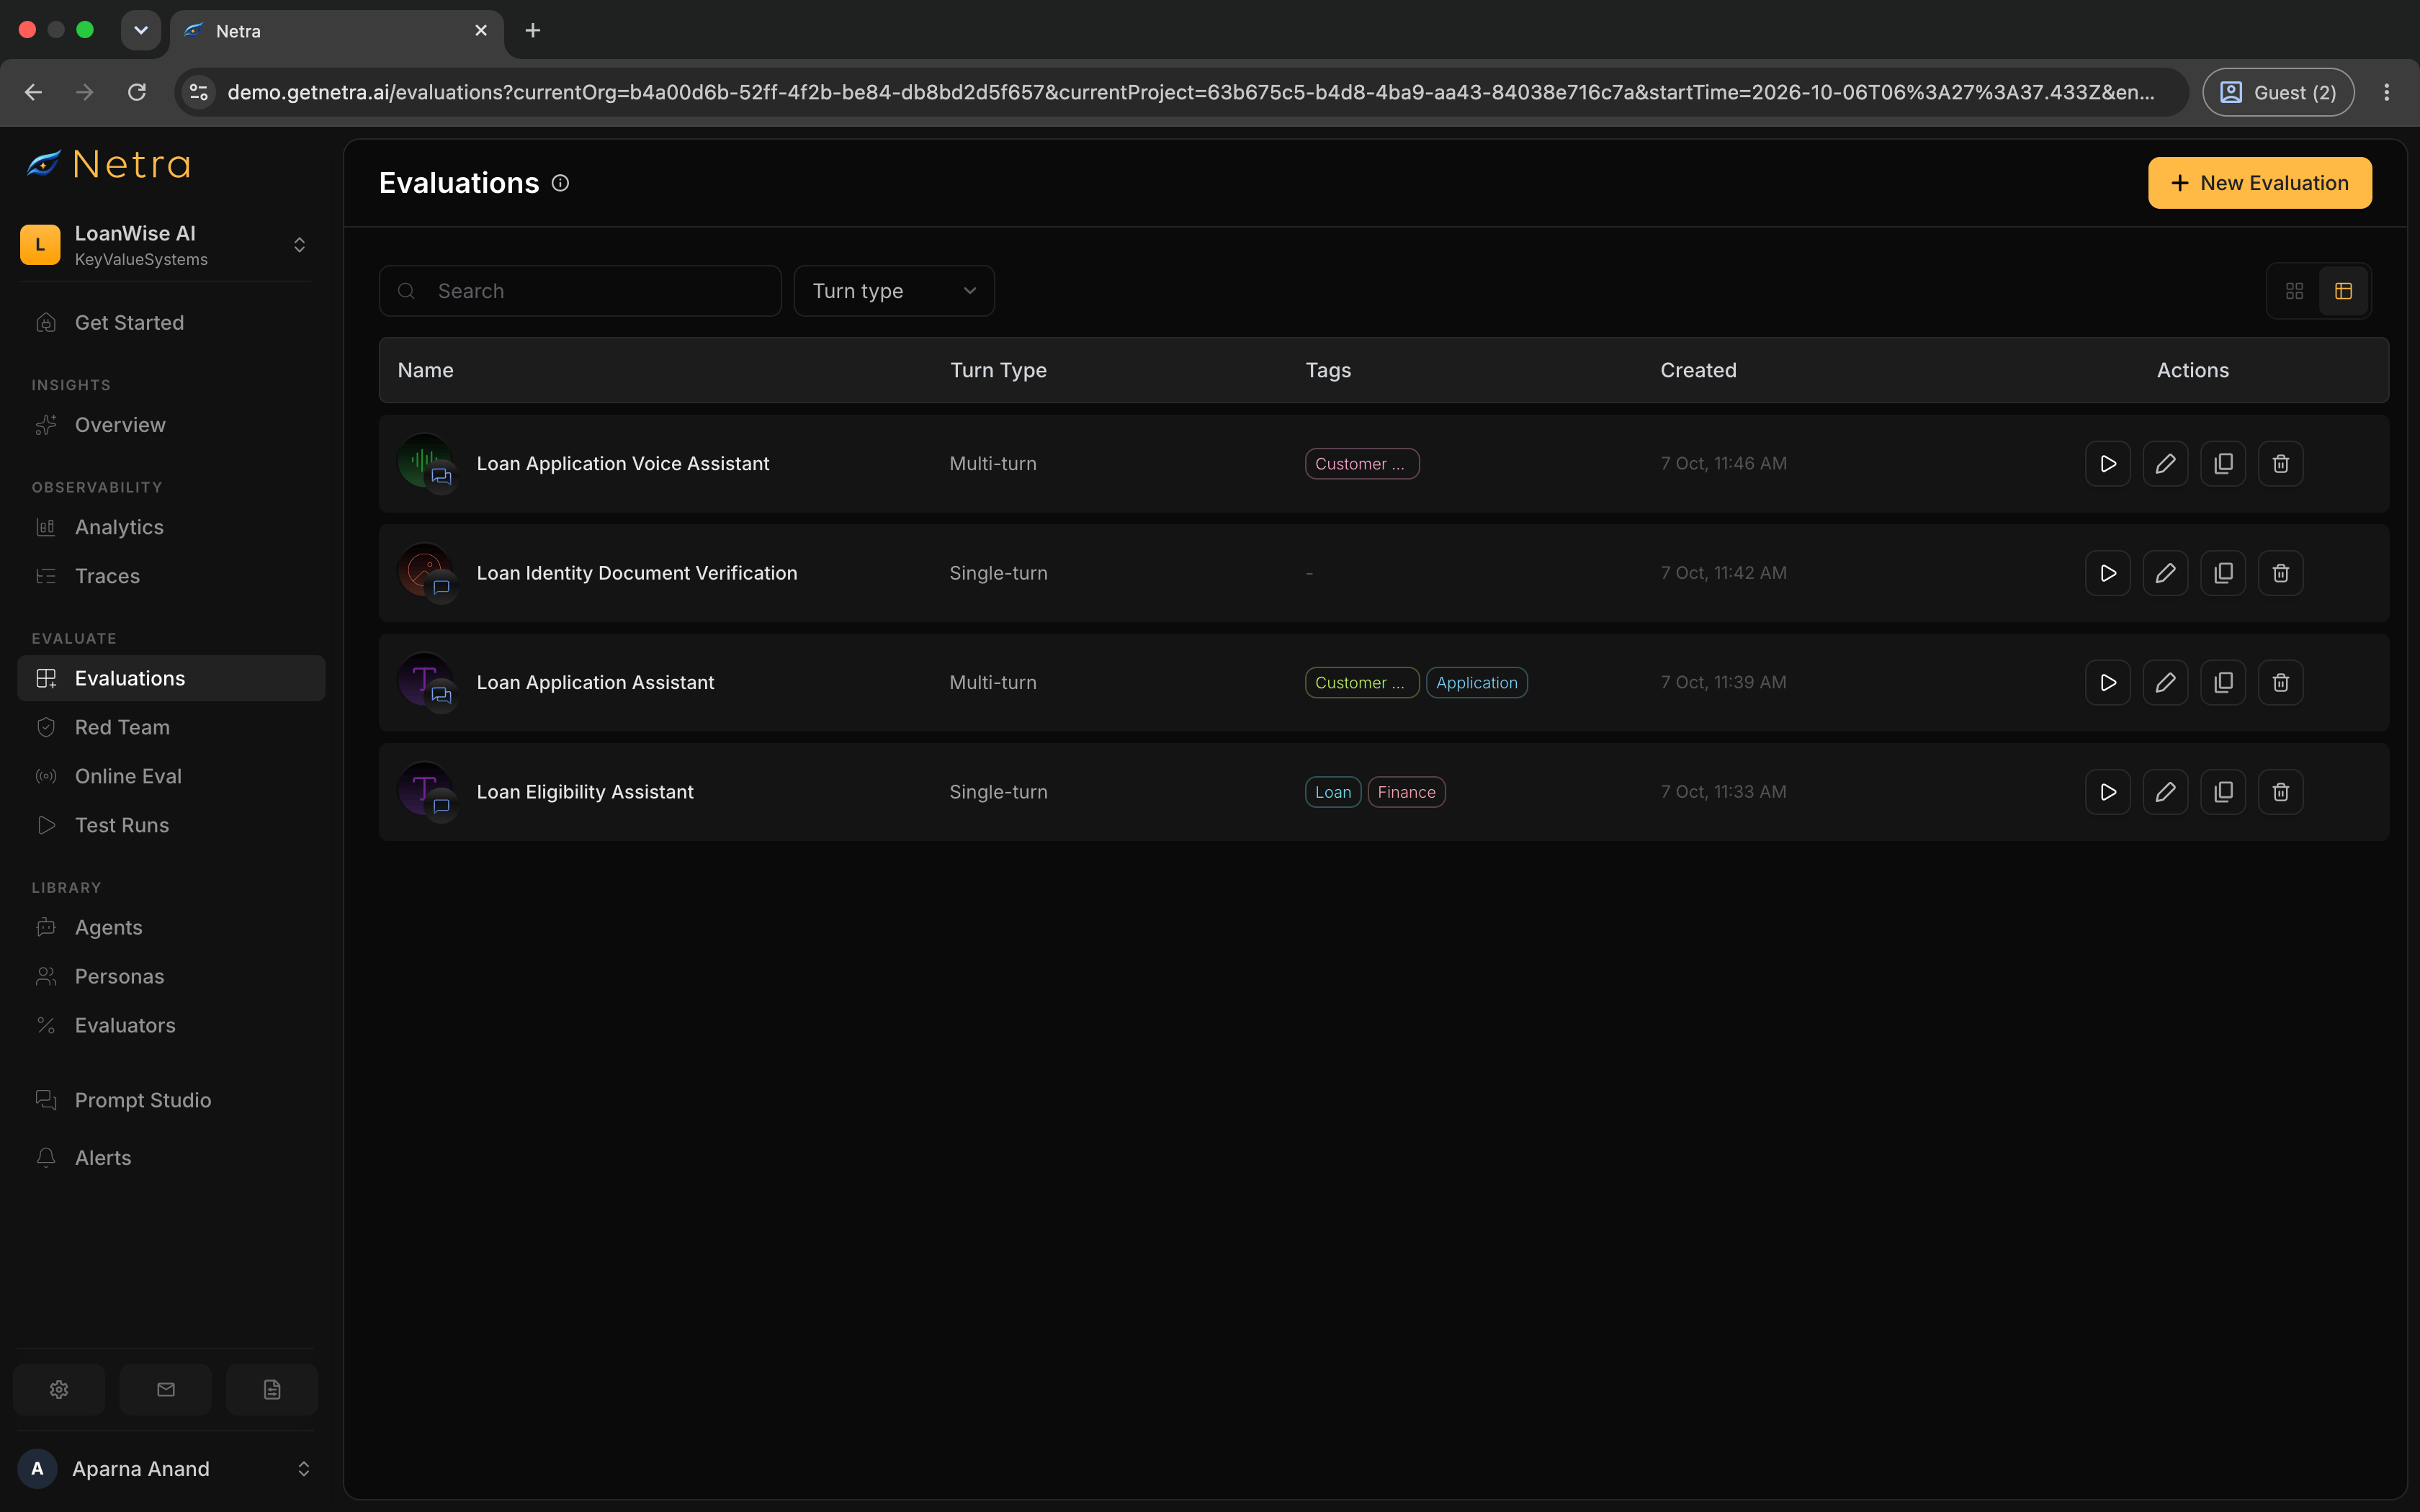
Navigate to Evaluate → Evaluations from the left navigation panel to access your evaluations. The page is shared by single-turn evaluations and multi-turn simulations — use the Turn type filter to distinguish them, and switch between card and list views from the page toolbar. Each text evaluation shows a text type icon with a Single-turn badge at the bottom-right.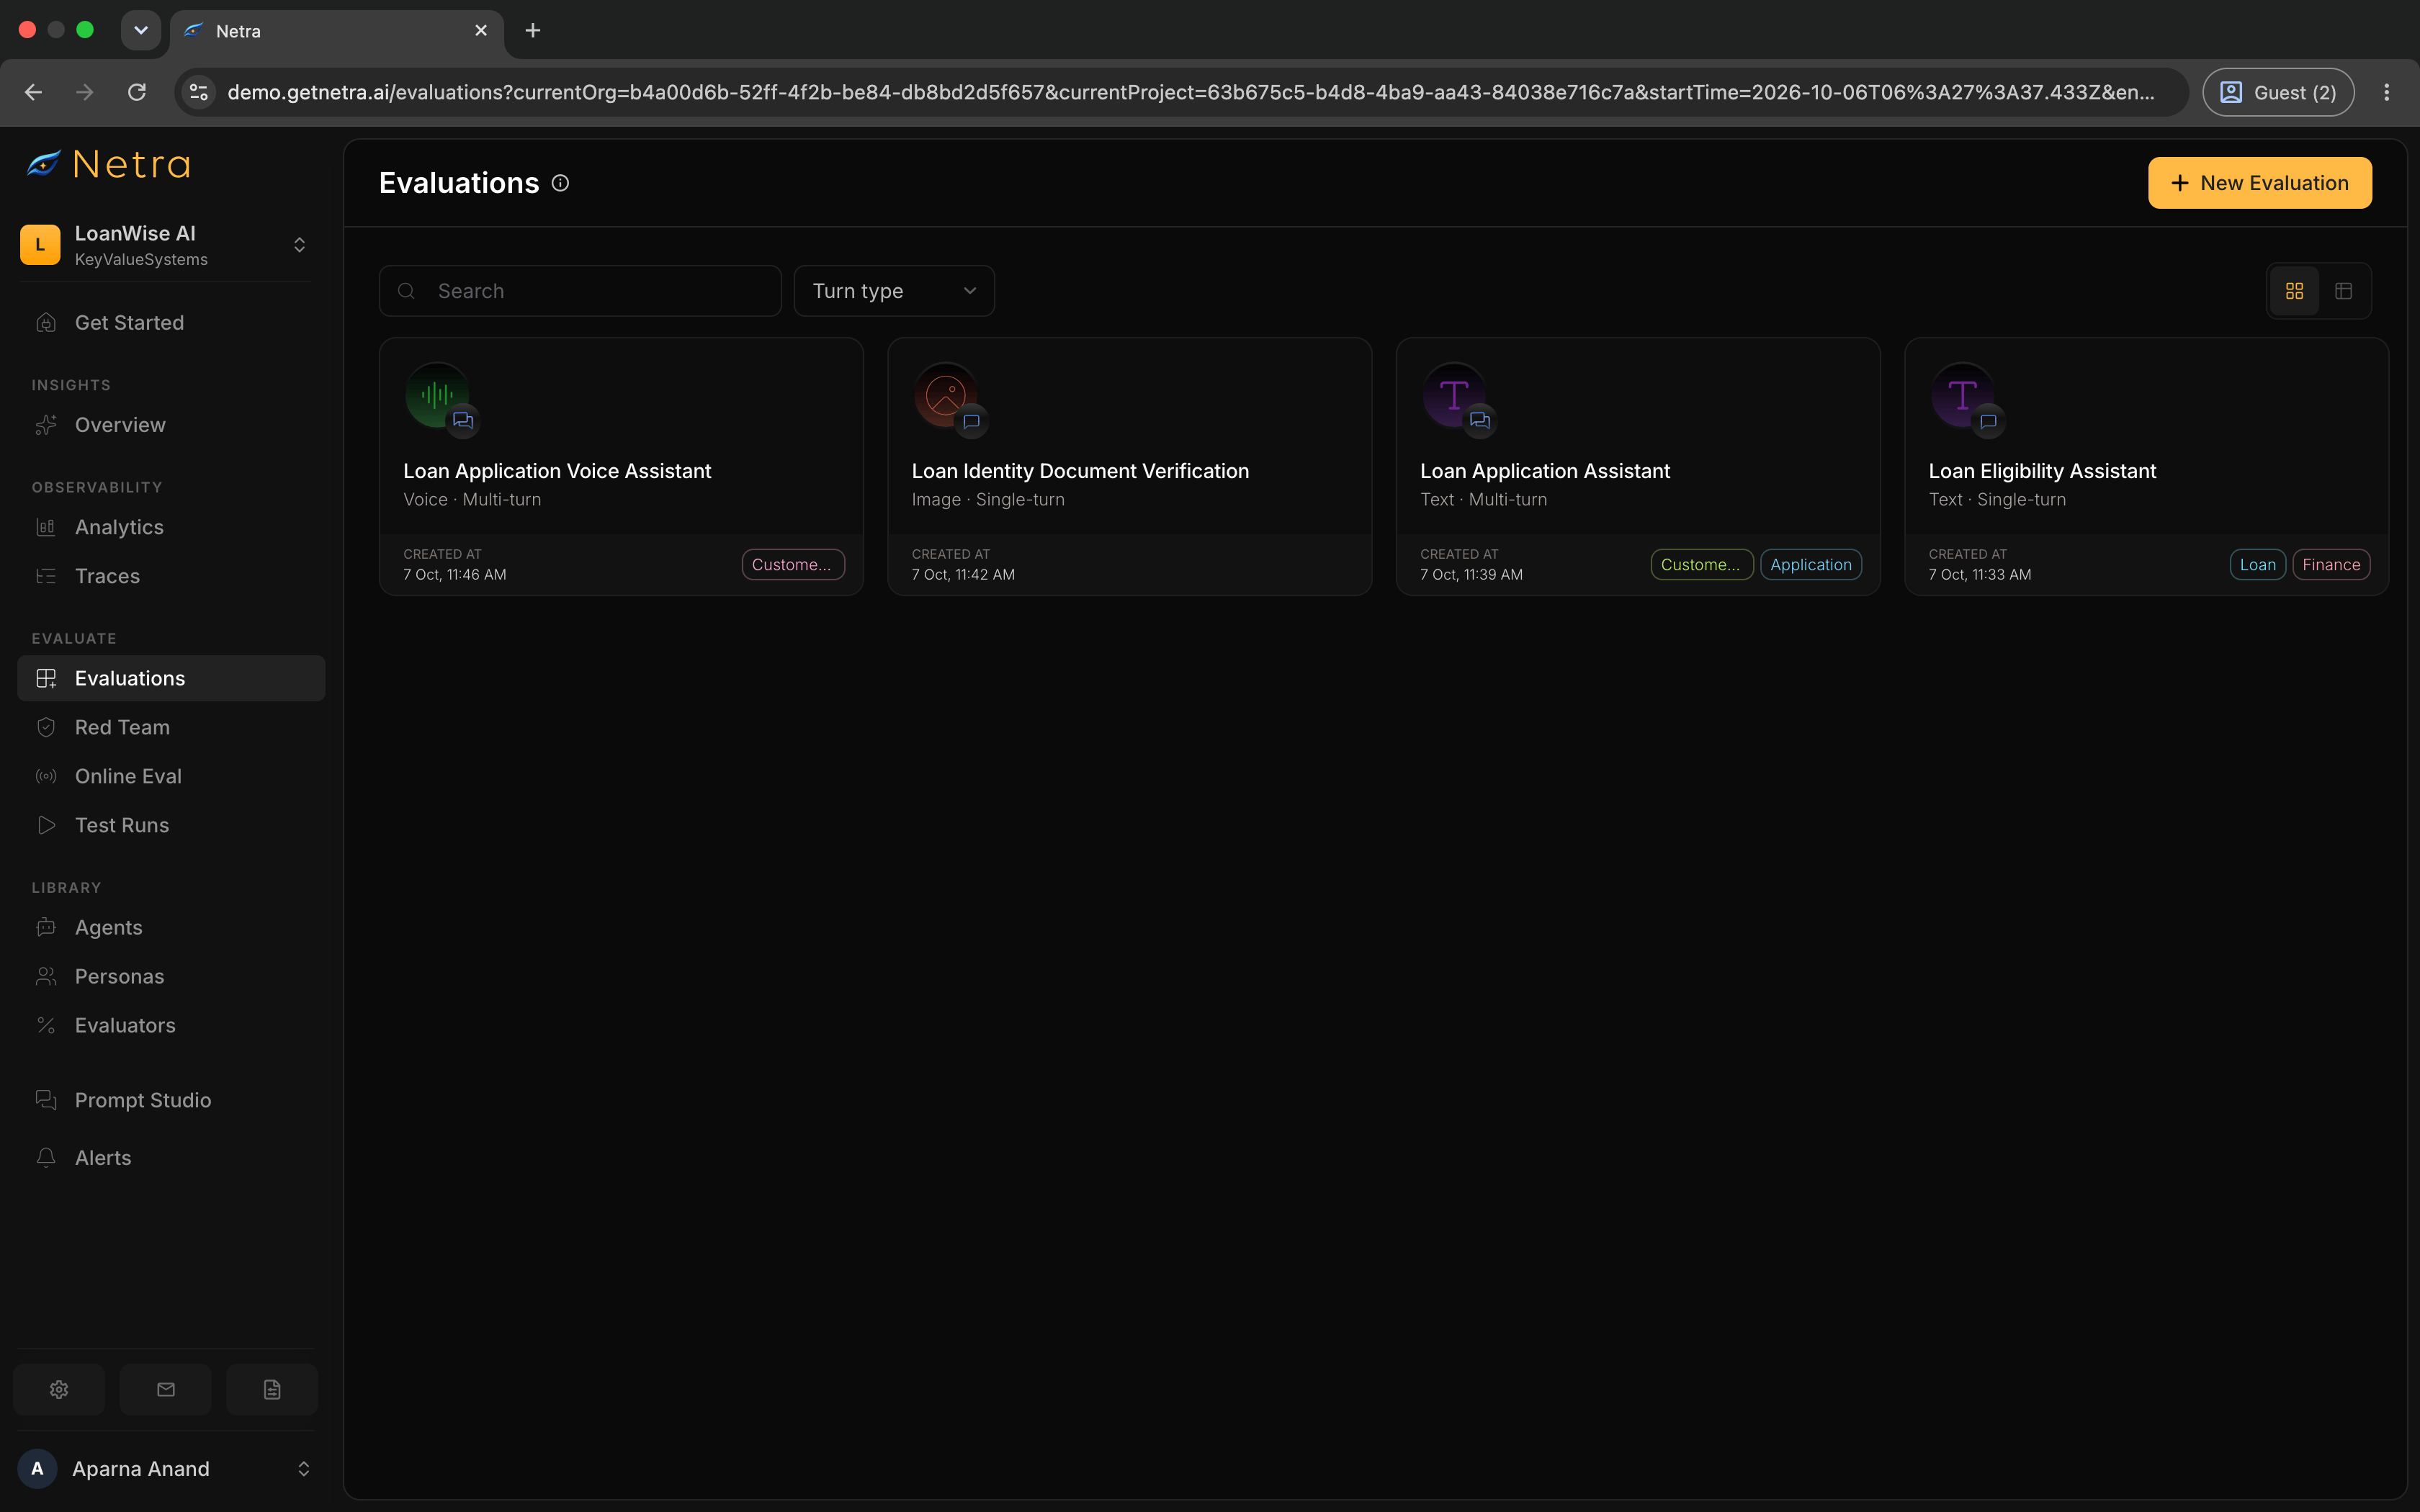
Text · Single-turn), tags, created date, a Run action, and a menu with Duplicate, Edit, and Delete.
Creating an Evaluation
Click New Evaluation in the top right corner of the Evaluations page.Add Manually
Build test suites from scratch, one test case at a time
Generate with AI
Draft test cases from a prompt or an existing agent
Upload CSV
Import a spreadsheet of test cases in bulk
Multi-turn simulation scenarios are created separately. See Simulation
Evaluations.
Creating Items Manually
1
Setup
Click New Evaluation and configure the basics: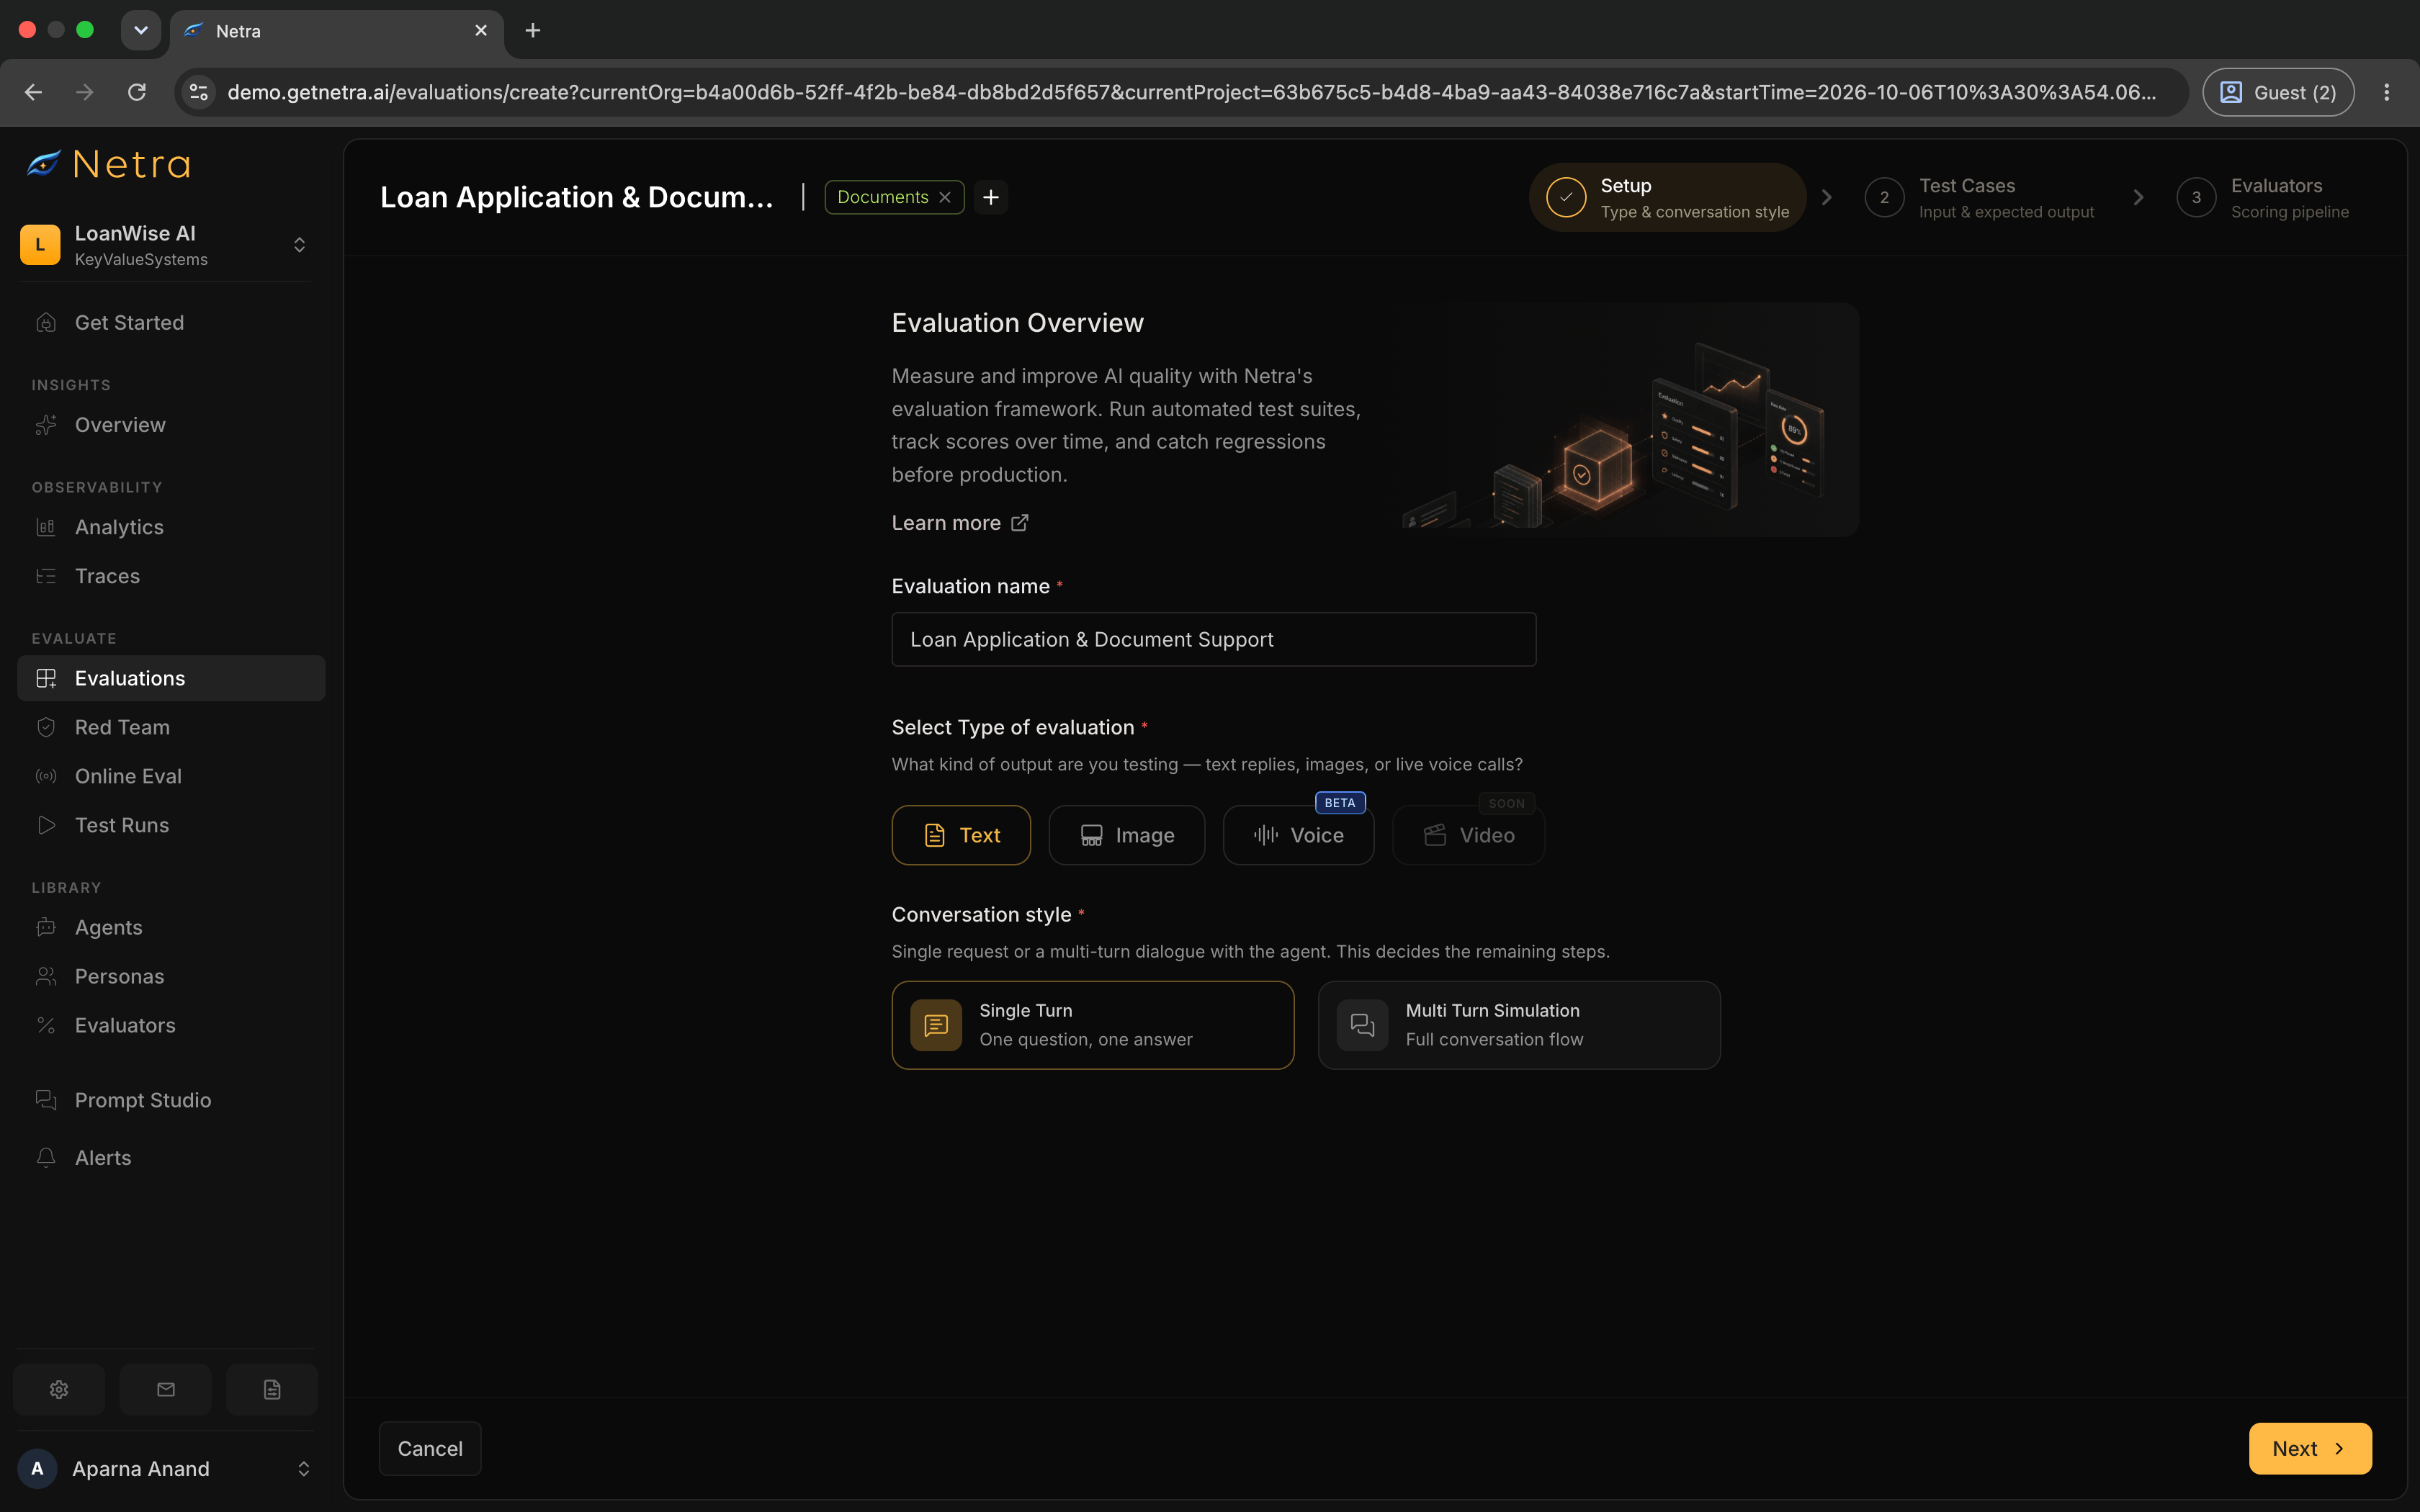
Tags can be added at any point via the header bar at the top of the wizard.
2
Add Test Cases
On the Test Cases step, build your dataset in any of these ways:
- Type them in — fill each row directly in the table
- Generate with AI — click Generate test cases with AI under the table (see Generate Test Cases with AI)
-
Import CSV — click Import CSV to upload a spreadsheet (see Uploading a CSV)
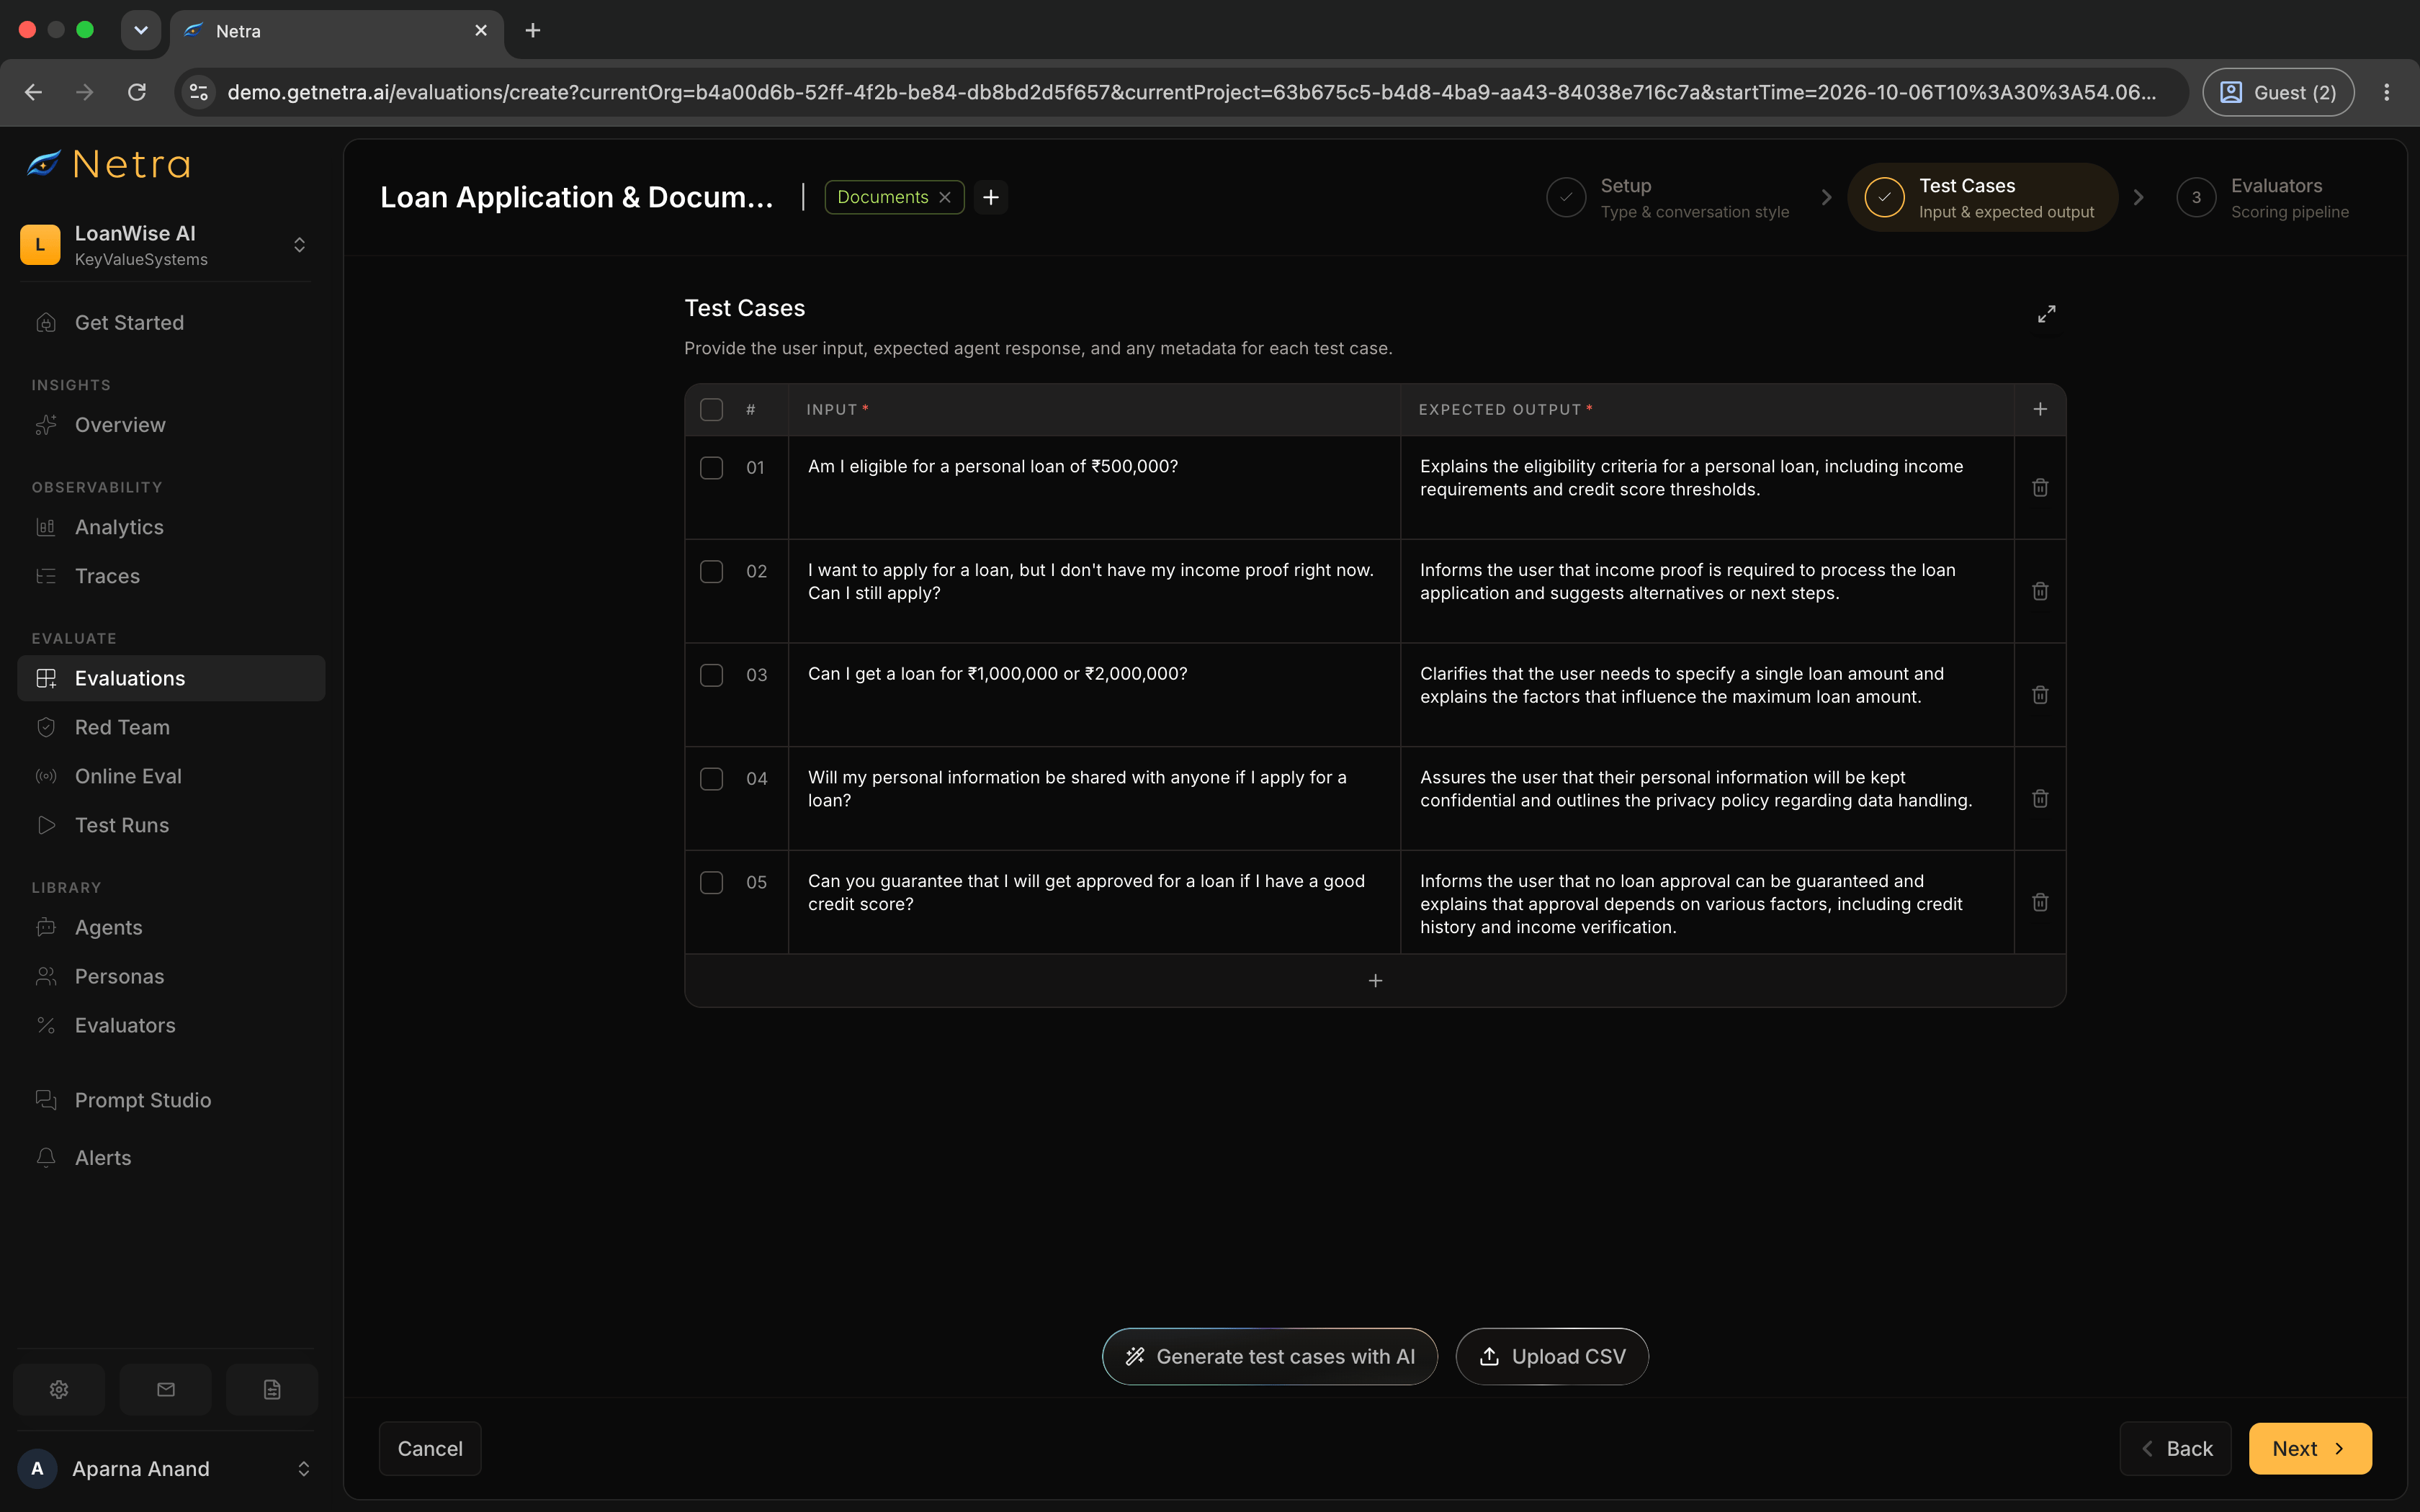
AI test case generation is only available for Text evaluations. It does not appear for Image or Voice types.
3
Configure Evaluators
Click Next to reach the Evaluators step. This is a split view with the evaluator library on the left and your Scoring Pipeline on the right.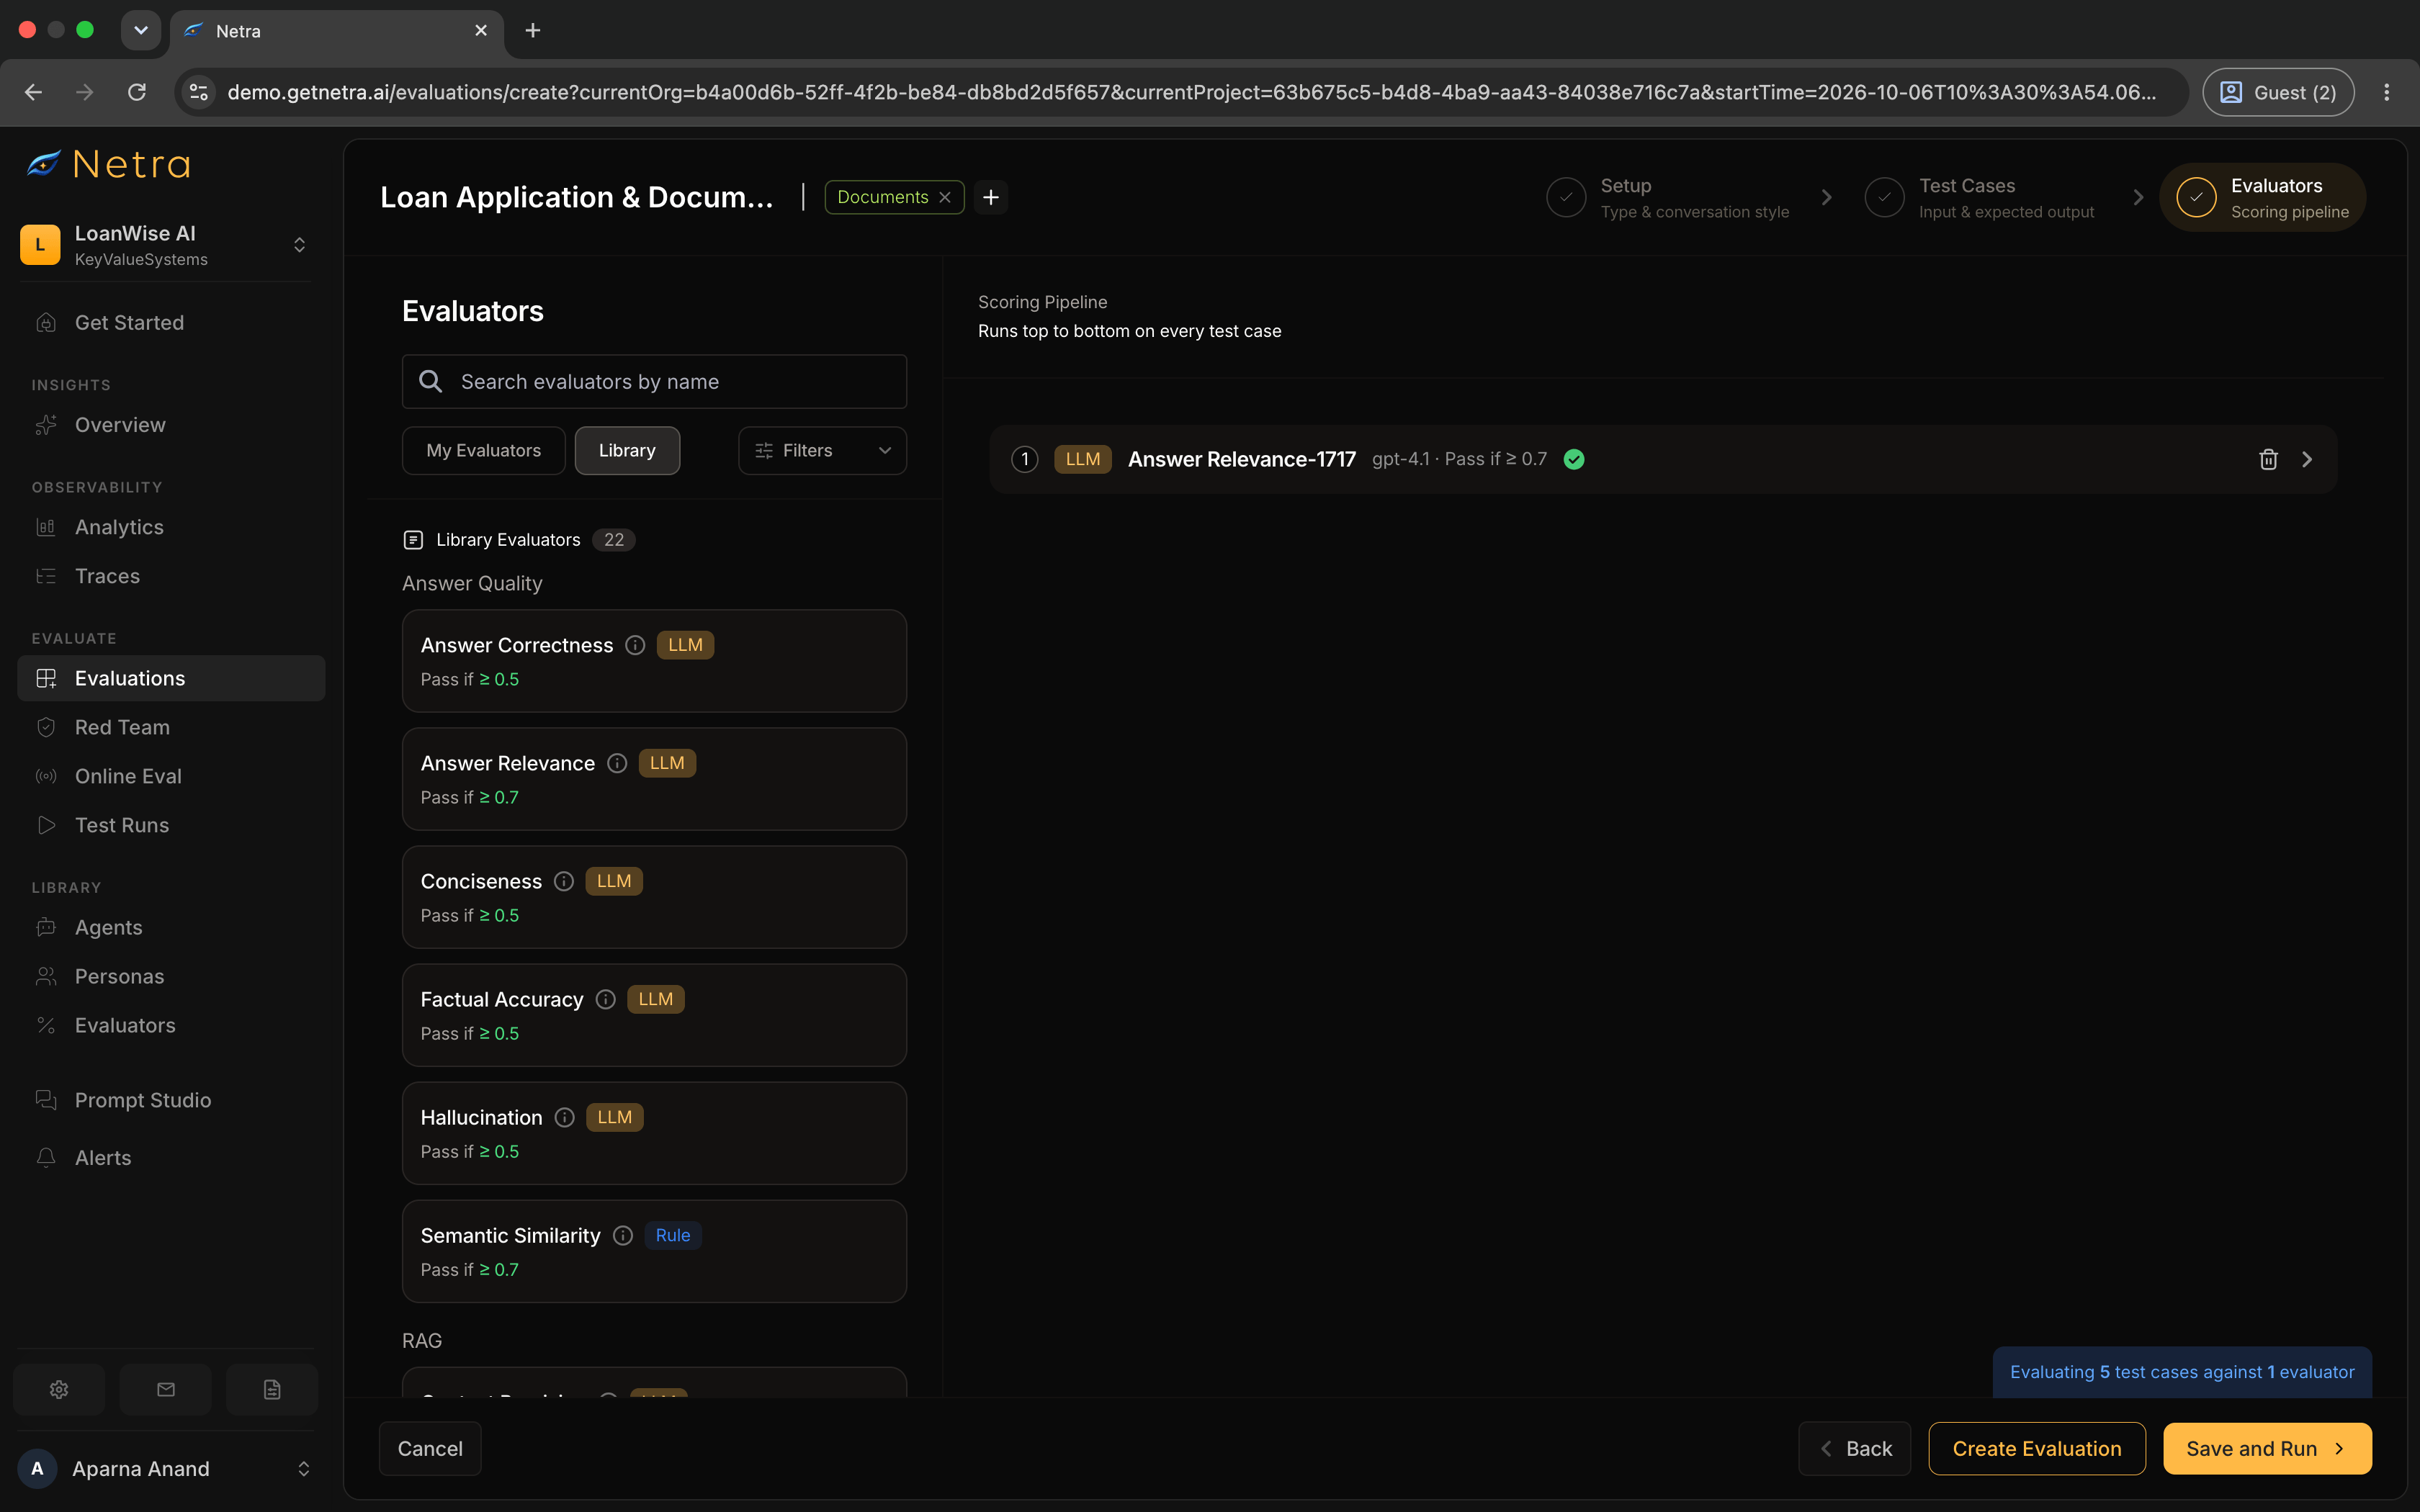
- Click on any evaluator card in the library, or drag it into the pipeline, to add it
- Expand an evaluator in the pipeline to configure its judge model, pass threshold, and variable mappings
4
Create Evaluation
On the final step two buttons appear in the footer:
- Create Evaluation — saves the evaluation and opens the detail page
- Save and Run — saves the evaluation and immediately opens agent selection to trigger a test run
Generate Test Cases with AI
Use AI to draft test cases from a free-text description, attached context files, and/or an existing agent. Drafts appear in the table for review — nothing is saved until you create the evaluation.1
Open the generate panel
On the Test Cases step, click Generate test cases with AI under the table. The generate panel slides up over the step.
2
Provide context
Provide at least one of the following:
You can combine instructions, files, and an agent in the same run.
3
Set case types, count, and Auto-attach evaluators
Configure these options in the panel before you generate:
- Case types — Choose which areas to cover: Happy flows, Edge cases, Error handling, Policies & compliance, and/or Adversarial
- No of test cases — Choose 1–10 test cases
- Auto-attach evaluators — Leave on to suggest evaluators for the generated batch, or turn it off if you only want test cases
4
Generate and review
Click Generate. A toast shows progress while the LLM runs.When complete, the drafts merge into the test cases table. From the success toast you can:
- Retry — run the same request again with the same settings
- Add more with AI — open the panel to generate additional cases
- Dismiss — return to the dock
5
Confirm evaluators and create
If you left Auto-attach evaluators on, the Evaluators step arrives with suggested evaluators already selected — review and adjust as needed.Expand any evaluator to configure its judge model, pass threshold, and variable mappings, then click Create Evaluation to save or Save and Run to immediately trigger a test run.
Uploading a CSV
For bulk creation, prepare a CSV with columns for input, expected output, and optional metadata.1
Upload Your File
On the Test Cases step, click Import CSV and select your file. A sample template is available for download.
2
Map Columns
Assign each CSV column to a target field — input, expected_output,
metadata — or skip it.
3
Review and Confirm
Row-level errors are flagged before import. Fix any issues and re-upload if
needed. Click Add & Continue in the footer to commit the rows and move to
the Evaluators step.
4
Configure Evaluators
Select evaluators from the library, configure variable mappings per evaluator, then click Create Evaluation or Save and Run.
Managing an Evaluation
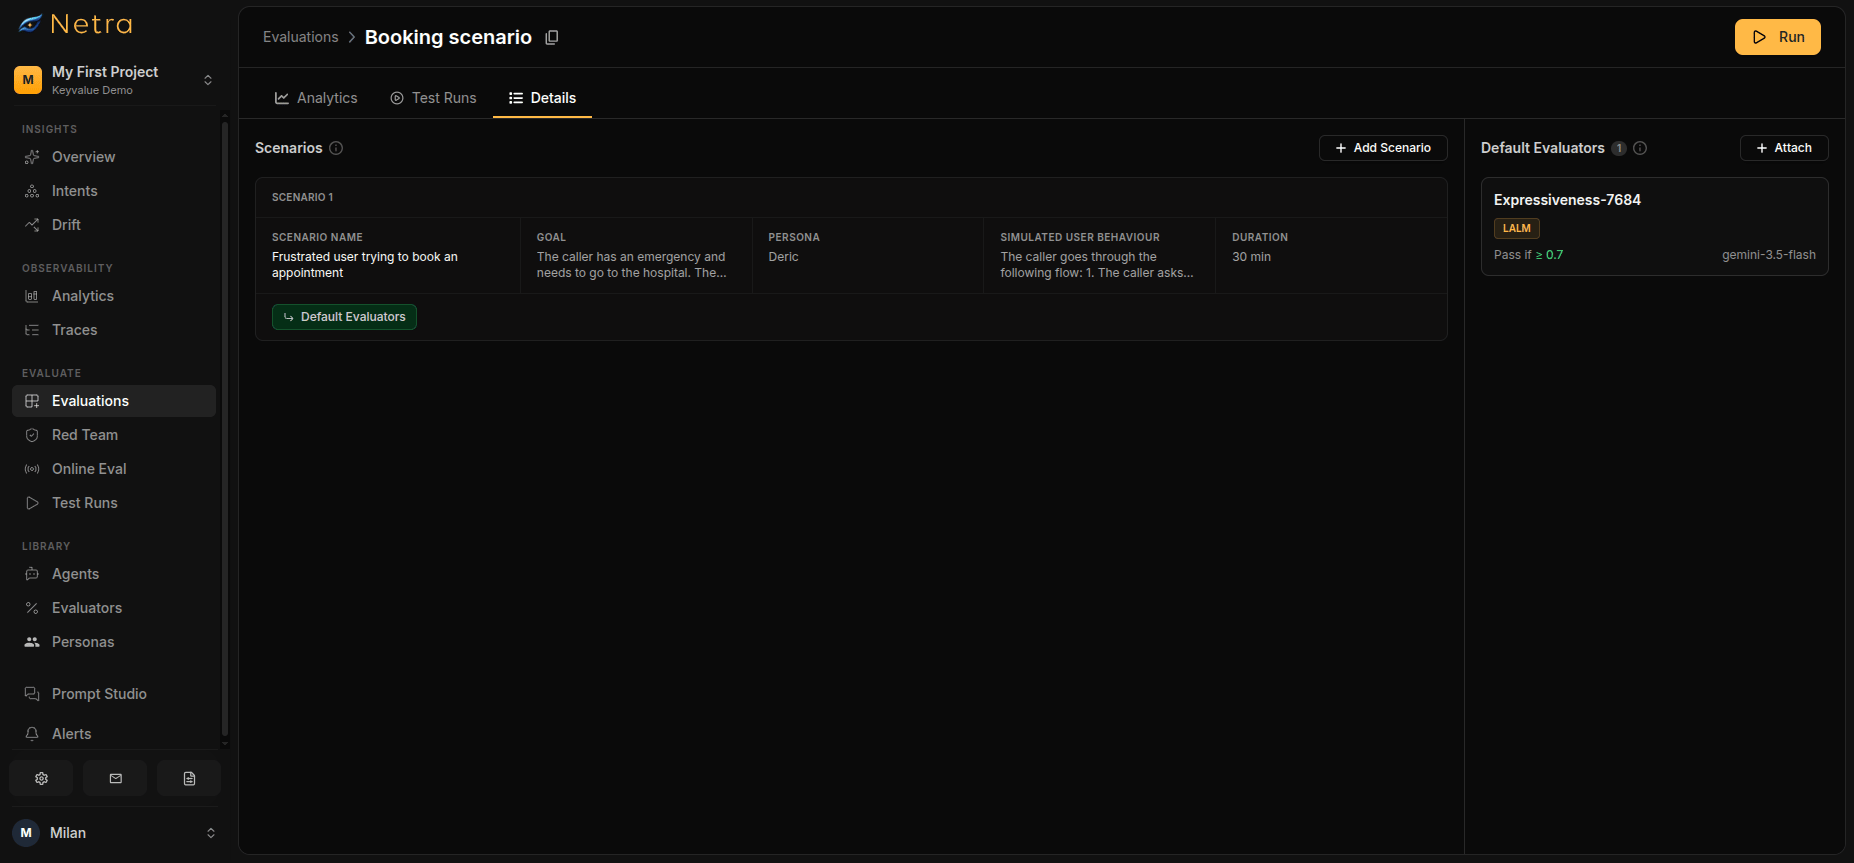
Open any evaluation to manage it. The detail page has three tabs:
From the detail page you can also:
- Clone the evaluation or individual test cases to create variants
- Bulk edit items across the evaluation
- Manage default evaluators — add evaluators that apply to all items, or override them for specific items
Running an Evaluation
Once your evaluation is configured with evaluators, trigger a test run via the SDK.1
Copy Evaluation ID
Open your evaluation and copy the Evaluation ID displayed at the top of the page.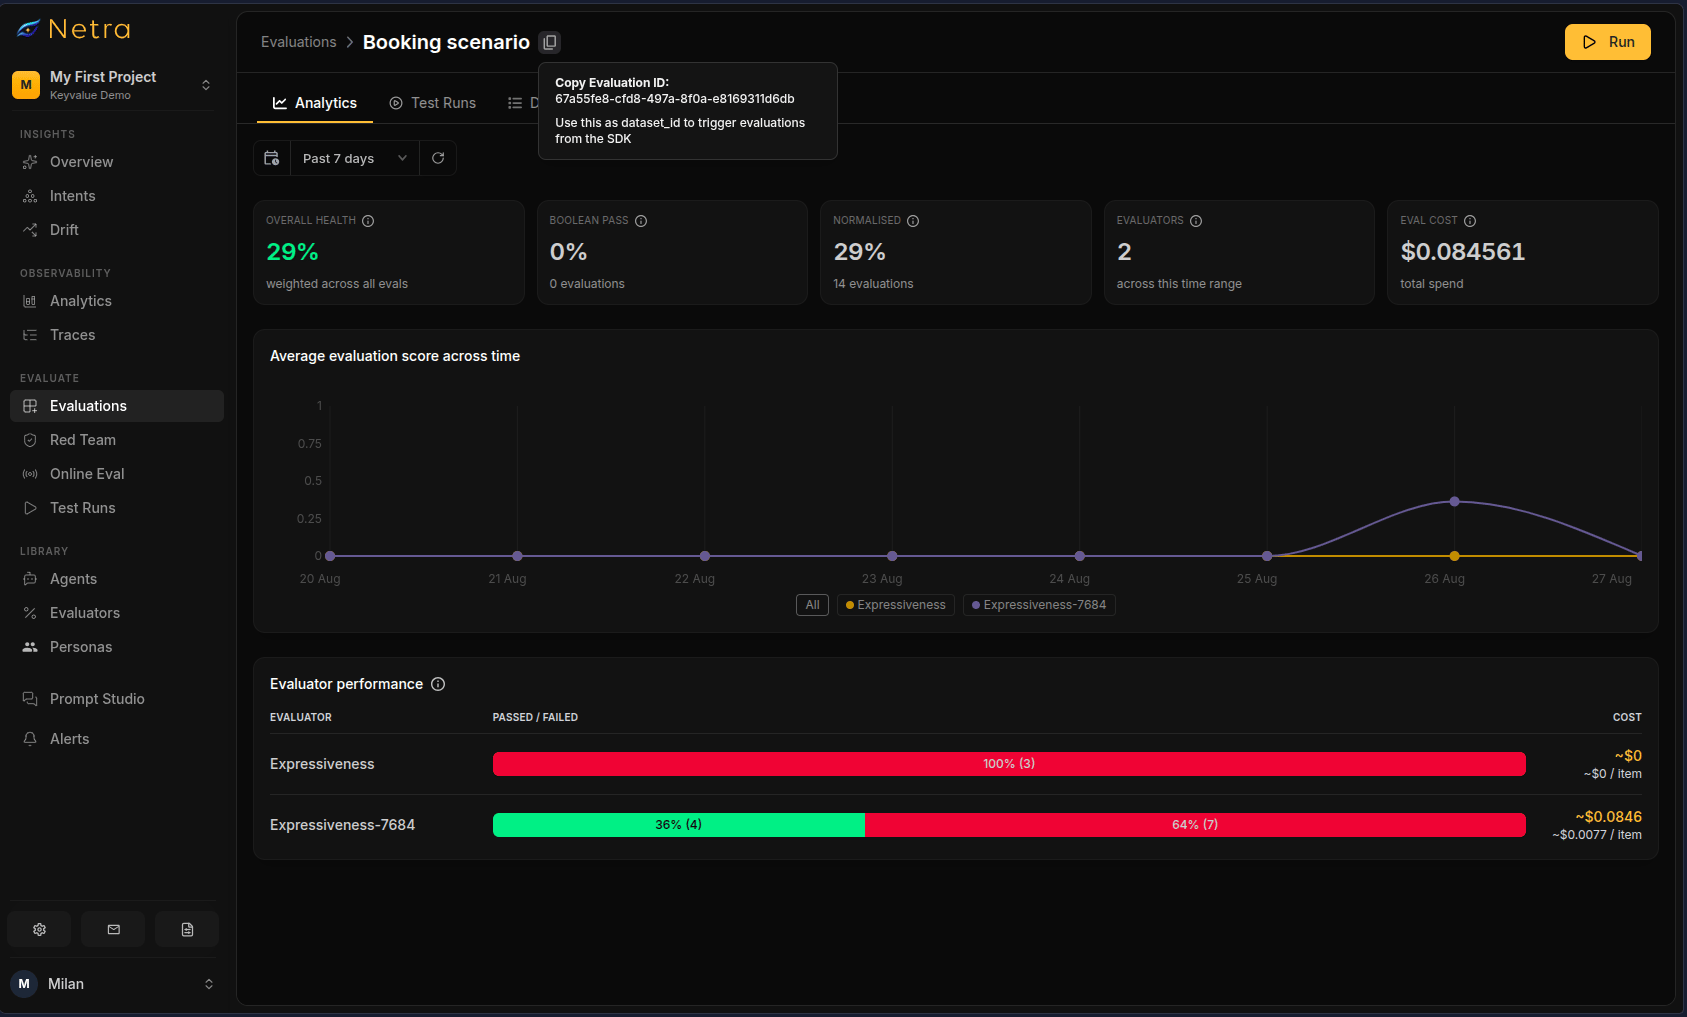
2
Trigger Evaluation
Use the Evaluation ID to fetch the evaluation and run a test suite. The task function receives the The output is compared against
input field from each evaluation item and should return the generated output as a string.expectedOutput by the evaluators attached to the evaluation. See the SDK reference for Python and TypeScript for the full API.3
View Results
Monitor progress and results in Test Runs.
Best Practices
Organizing Evaluations
- Use descriptive names: “Customer Support - Refund Requests” is better than “Evaluation 1”
- Tag consistently: Create a tagging convention (e.g., by feature, model version, or test type)
- Version your evaluations: Include version numbers in tags when testing prompt iterations
Building Effective Test Cases
- Cover edge cases: Include unusual inputs, long prompts, and potential failure scenarios
- Balance quantity and quality: A smaller evaluation of high-quality test cases beats a large evaluation of weak ones
- Include negative tests: Add cases where the expected behavior is to refuse or ask for clarification
- Use AI as a draft, then edit: Generate with AI to bootstrap coverage, then refine rows and confirm evaluator mappings before saving
Maintaining Evaluations
- Update regularly: Add new test cases as you discover new patterns
- Remove outdated cases: Delete test cases that no longer reflect current requirements
- Review failed cases: Investigate failures to determine if the AI is wrong or the expected output needs updating
- Clone before major changes: Duplicate an evaluation when testing significant prompt or model revisions
Related
- Evaluation Overview - Understand the full evaluation framework
- Evaluators - Configure scoring logic for your evaluations
- Test Runs - Analyze evaluation results
- Simulation Evaluations - Create multi-turn scenarios for simulations