Why Simulations Matter
Simulations transform simple Q&A testing into realistic conversation testing:Simulation Dashboard
Navigate to Evaluate → Evaluations from the left navigation panel. Filter by Multi turn type to see simulations.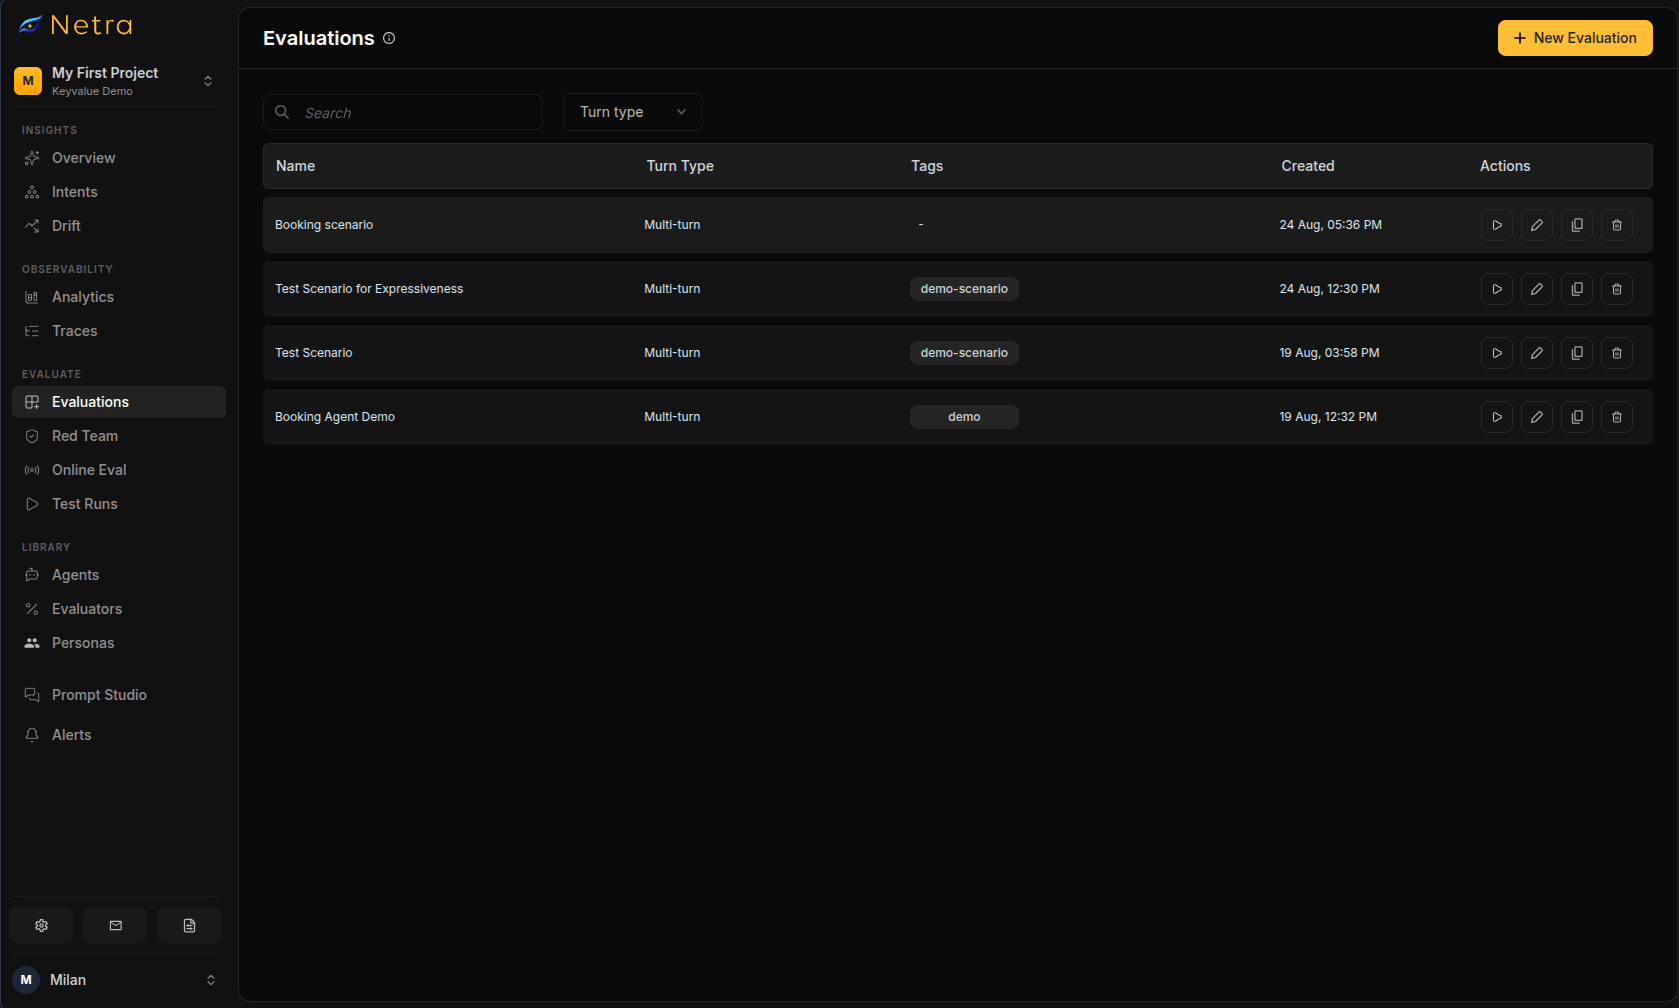
Creating a Multi-Turn Simulation
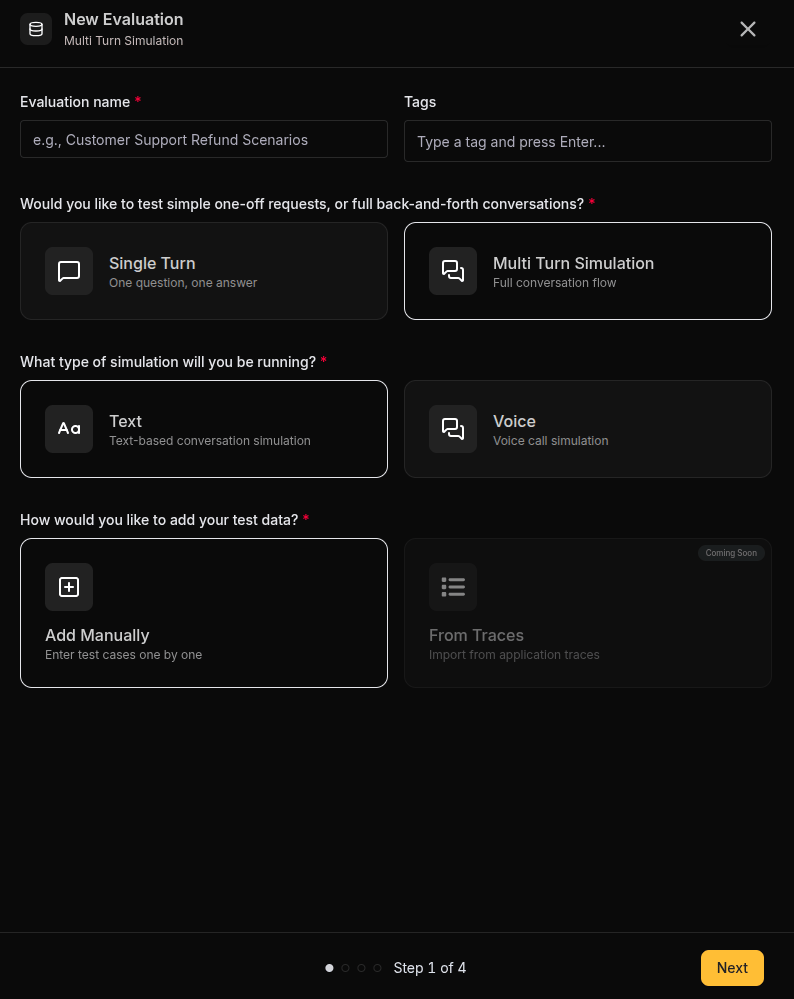
Click New Evaluation in the top right corner of the Evaluations page, then select Multi Turn Simulation.Add Manually
Build simulation scenarios from scratch, one scenario at a time
1
Configure Basics
2
Set Up Your Test Scenario
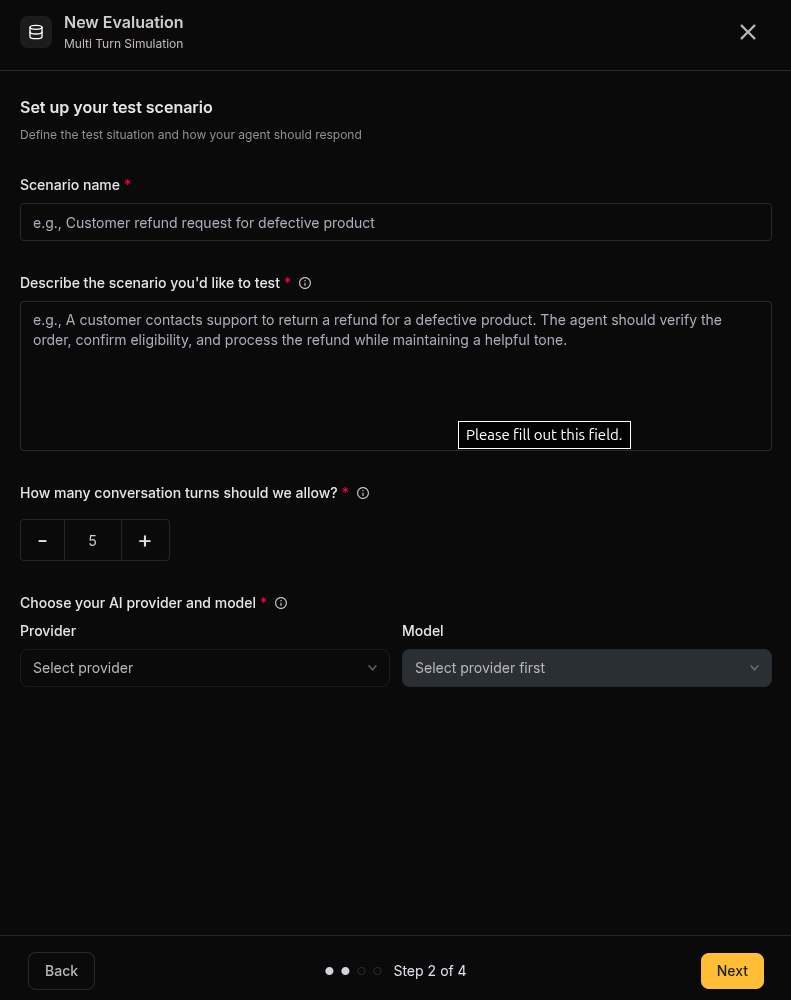
- Lower (1-10): Quick interactions and single-question support
- Medium (11-25): Standard support conversations
- Higher (26-50): Complex, multi-step problem resolution
3
Set Up the Simulated User
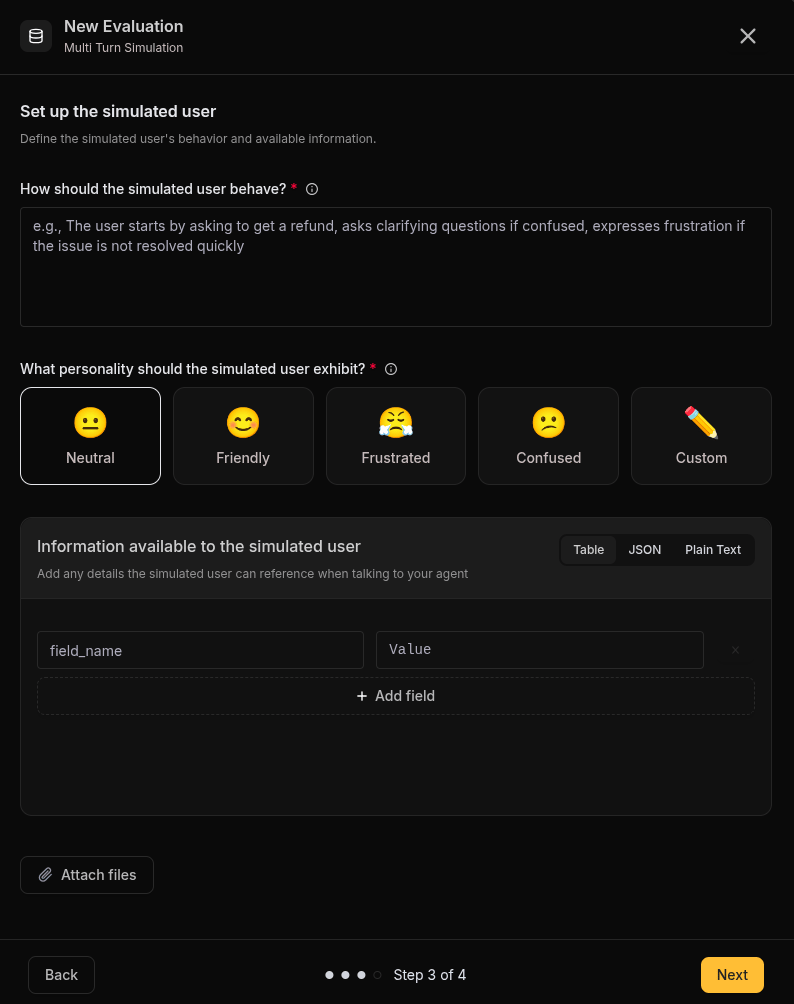
Information available to the simulated user — Provide the context data the simulated user can reference during the conversation. Enter it as a Table, as JSON, or as Plain Text.Example (Table):
Example (JSON):
4
Choose Your Evaluators
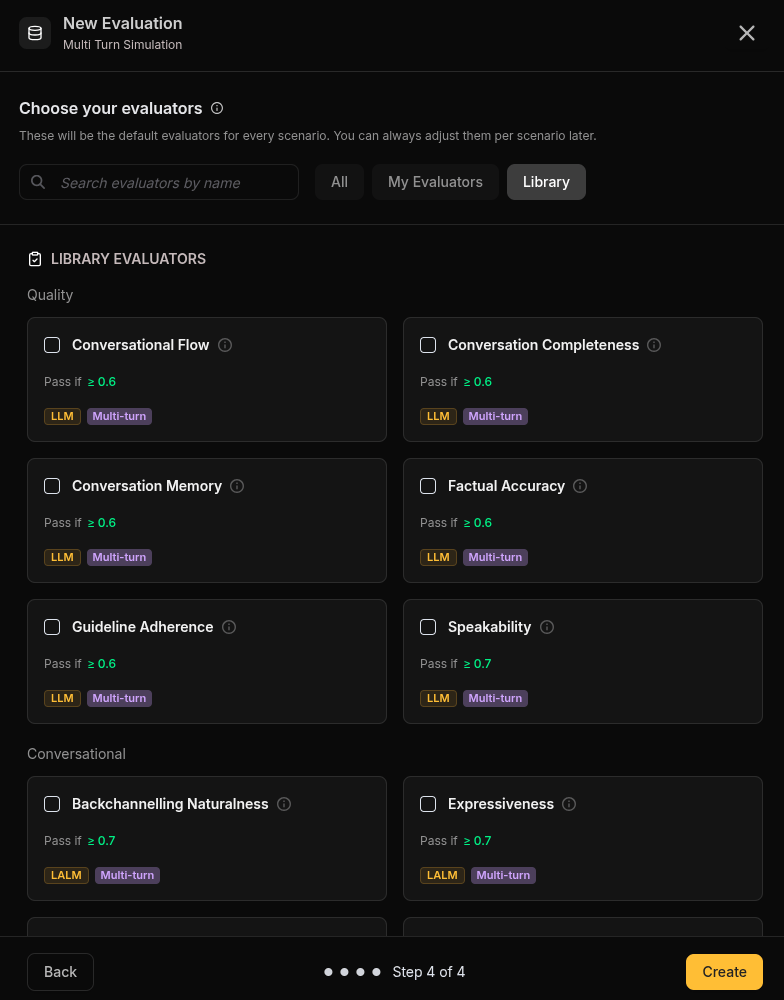
- Conversational Flow — Evaluates the natural flow of conversation
- Conversation Completeness — Checks if the conversation reaches a complete resolution
- Conversation Memory — Tests if the agent remembers context across turns
- Factual Accuracy — Verifies the agent communicates correct information
- Guideline Adherence — Checks if the agent follows specified guidelines
- Speakability — Evaluates how natural the agent’s responses sound
- Backchannelling Naturalness — Tests natural backchanneling responses
- Expressiveness — Evaluates emotional expressiveness in responses
5
Review & Finalize
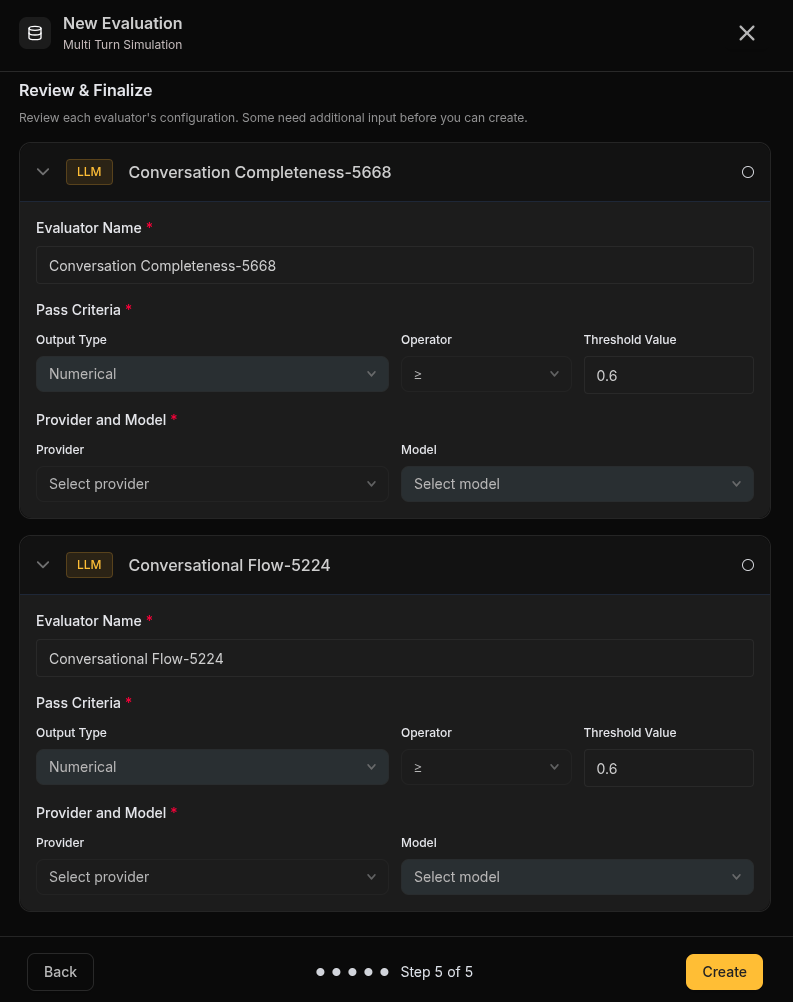
- Evaluator Name — Match your use case (e.g., “Refund Goal Fulfillment” instead of “Goal Fulfillment”)
- Pass Criteria — Configure the output type (Numerical), operator (≥), and threshold value
- Provider and Model — Choose the model that runs each LLM-as-Judge evaluation
- Guideline Adherence: your agent’s instructions and constraints
- Factual Accuracy: the reference facts your agent must communicate correctly
Running a Simulation
Once your simulation is configured, you can run simulations from the dashboard or the SDK.From the Dashboard
1
Open Run Test Suite
Open your simulation, go to the Test Runs tab, and click Run Test Suite.
2
Select an Agent and Name the Run
Pick a registered agent to converse with the simulated users, give the run a name, and start it. Netra runs every scenario and evaluates each conversation.
3
View Results
Monitor progress and results in Test Runs.
From the SDK
Use the SDK’s simulation methods with your Simulation ID to trigger simulations from your own code. See the SDK reference for Python and TypeScript.Managing a Simulation
Open any simulation to manage it:
You can also clone scenarios or the entire simulation to create variants.
Best Practices
Crafting Effective Scenarios
- Be specific: “Get a refund for a damaged product” is better than “Ask about returns”
- Include context: Provide enough detail for realistic simulation (order details, timeline, issue description)
- Include edge cases: Create scenarios that challenge your agent’s boundaries
Choosing User Personas
- Neutral: Best for baseline performance testing
- Friendly: Tests whether your agent maintains professionalism even when not challenged
- Frustrated: Critical for customer support agents—tests patience and de-escalation
- Confused: Tests clarity and explanation quality
- Custom: Use for industry-specific personas (technical users, non-native speakers, etc.)
Defining User Data
- Provide realistic data: Use representative order numbers, dates, and values
- Include edge cases: Test with missing fields, unusual values, or conflicting data
- Keep it relevant: Only include data that matters for the scenario
- Use consistent formats: Standardize date formats, currency, and naming
Verifying Facts
To check that your agent communicates critical information correctly:- Attach the Factual Accuracy evaluator and provide the must-communicate facts as its Reference Facts variable
- Focus on critical facts: What MUST the agent get right?
- Be precise: “5-7 business days” is better than “about a week”
Related
- Simulation Overview - Understand the full simulation framework
- Evaluators - Configure scoring logic for simulations
- Test Runs - View simulation results and conversation transcripts
- Traces - Debug simulation turns with execution traces