What You’ll Learn
Connect a voice agent
Register your LiveKit, Vapi, or WebSocket front-desk agent in Netra so simulated calls can reach it — no SDK integration required.
Design caller personas
Build guests who talk fast, ramble, get frustrated, or call from a noisy airport with a non-native accent.
Score voice and outcome together
Combine voice evaluators (pronunciation, pace, transcription) with text evaluators (goal fulfillment, policy adherence).
Catch regressions before guests do
Re-run the same suite on every prompt change and track pass rates over time in Analytics.
Prerequisites
- A Netra account and API key — see Quick Start
- A running hotel front-desk voice agent on LiveKit, Vapi, or a custom WebSocket
- Credentials for that agent (LiveKit server URL + API key/secret, Vapi API key + assistant ID, or WebSocket URL + auth token)
- Provider keys for the STT and reasoning models used to drive the simulated caller
Voice simulations in Netra are configured in the UI, not through the SDK. Netra places the simulated calls to your agent, records the conversation, transcribes it, and runs evaluators against the result. You do not need to instrument your agent code to run this cookbook.
Why Simulate Voice Calls?
Text evaluation catches reasoning failures. Voice evaluation catches everything that happens between the reasoning and the guest’s ear — and the guest only ever experiences the latter.Step 1: Connect Your Front-Desk Agent
Netra needs to be able to reach your agent to call it. Go to Library → Agents → Add Agent and choose your platform.- LiveKit
- Vapi
- WebSocket
Describe the application
Below the platform credentials, fill in Application Details. Netra uses these to generate realistic callers and to understand where the boundaries are. For a hotel front desk: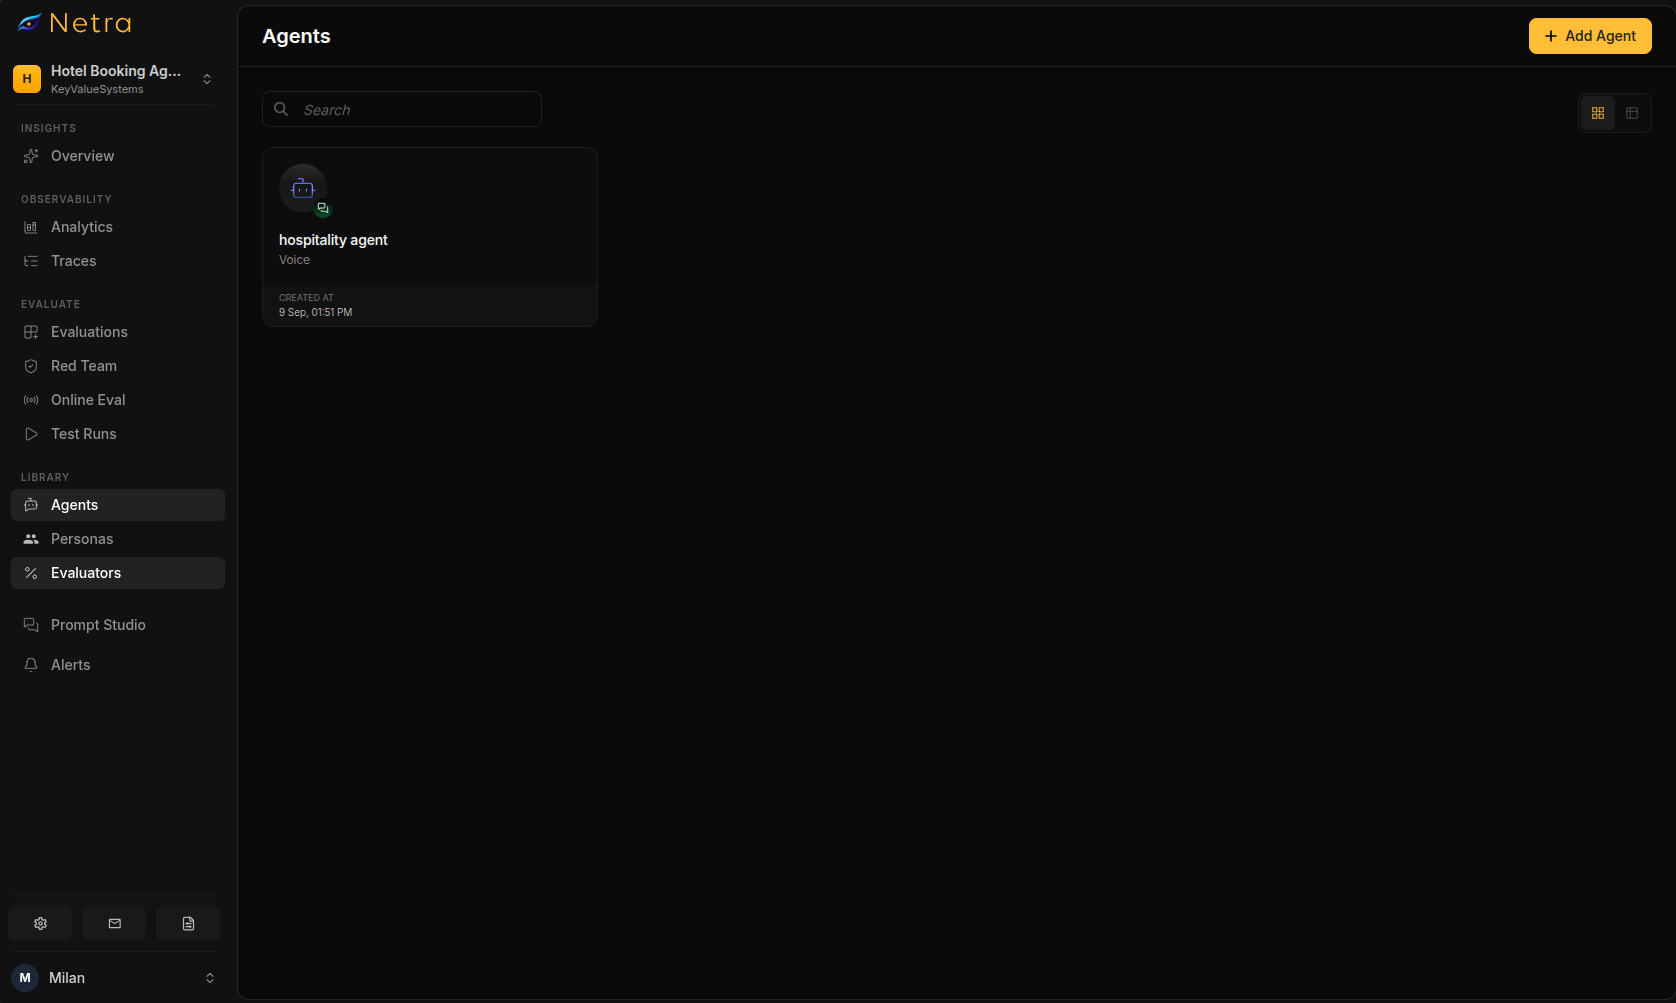
A connected front-desk agent in Library → Agents
Step 2: Build Your Caller Personas
A persona controls how a caller speaks. The scenario controls what they want. Keeping them separate means you can run the same booking scenario as a calm guest and as a frustrated one, and see where the agent breaks. Go to Library → Personas → New Persona. Each persona has four sections: identity, speech traits, voice, and knowledge. Here is the set this cookbook uses.Give the persona facts to work with
The Knowledge section holds key-value facts the persona can reference when the agent asks. If the agent asks for something that isn’t here, the persona will say it doesn’t know — which is exactly what you want, because it forces the agent to handle incomplete information. For Dana, the guest whose room isn’t ready: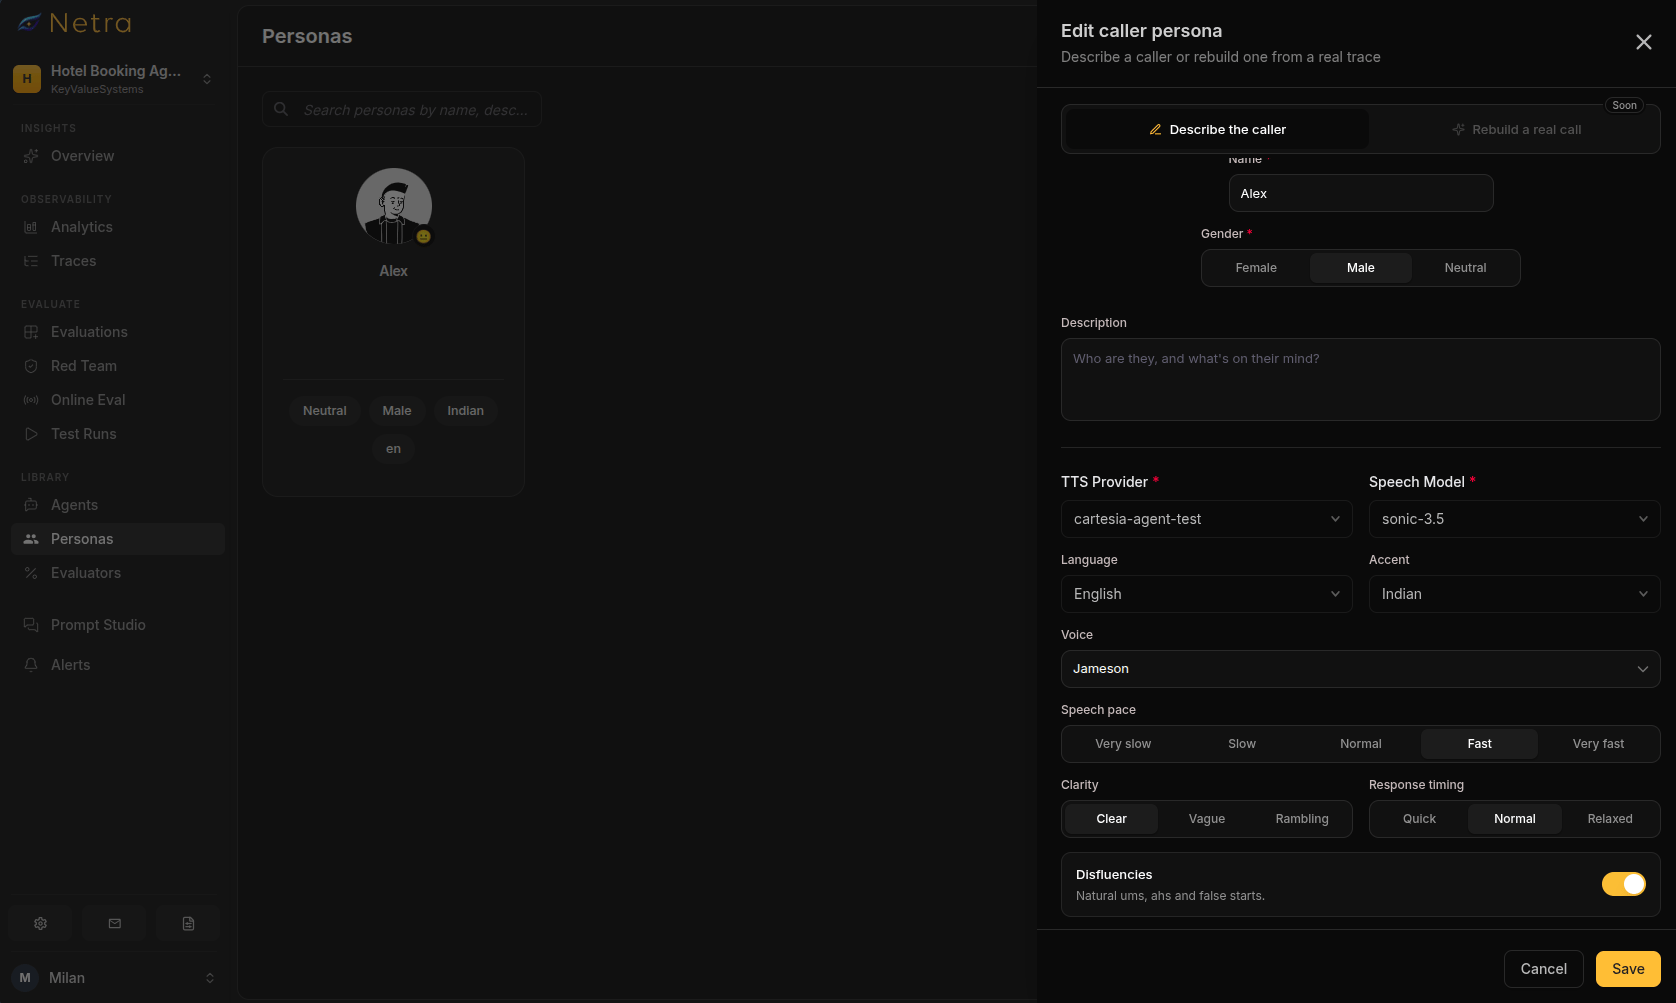
Configuring speech traits for a frustrated guest persona
Step 3: Create the Voice Evaluation
Go to Evaluate → Evaluations → New Evaluation and set:- Turn Type: Multi Turn Simulation
- Simulation Type: Voice
Add your scenarios
Each scenario pairs one persona with one goal. Netra’s guidance here is worth following literally: one goal per scenario. A scenario that asks the caller to book a room and dispute a rate and request late checkout will fail for reasons you can’t isolate.1
Baseline reservation
Persona: Priya · Max turns: 12 · Max duration: 4 min · Noise: noneBehaviour instructions: You want to book a standard king room for two nights starting next Friday. Answer the agent’s questions directly. Confirm the booking once you have heard the total rate.
2
Late checkout and upgrade
Persona: Marcus · Max turns: 10 · Max duration: 4 min · Noise: office, 0.3Behaviour instructions: You are a Platinum member arriving tomorrow. Ask for a 2 PM checkout and whether a suite upgrade is available. You are in a hurry and will speak quickly.
3
Room not ready — service recovery
Persona: Dana · Max turns: 14 · Max duration: 5 min · Noise: noneBehaviour instructions: You arrived at 11:20 AM and were told your room isn’t ready. You are tired and increasingly impatient. Escalate your frustration if the agent gives you a generic answer. You will accept luggage storage plus a lobby drink voucher, or a firm time commitment.
4
Non-native speaker at a noisy airport
Persona: Elena · Max turns: 16 · Max duration: 6 min · Noise: airport or street, 0.5Behaviour instructions: You want a room for tonight for two adults and one child. You are at an airport and it is loud. Spell your surname if the agent asks. You are unsure about dates and may correct yourself.
5
Rate dispute
Persona: Tom · Max turns: 12 · Max duration: 5 min · Noise: noneBehaviour instructions: You were quoted £180 per night last week but your confirmation shows £215. Ask the agent to honour the original quote. Do not accept a vague answer, but do accept an escalation to a manager.
6
Accessible room request
Persona: Ruth · Max turns: 12 · Max duration: 5 min · Noise: noneBehaviour instructions: You need a wheelchair-accessible room with a roll-in shower and grab bars for a three-night stay. Ask specifically whether the roll-in shower is guaranteed, not just requested.
7
Cancellation outside the free window
Persona: Kenji · Max turns: 12 · Max duration: 5 min · Noise: noneBehaviour instructions: You want to cancel a reservation that is inside the 48-hour penalty window. Ask for the fee to be waived. Push back once when refused, then ask what the fee actually is.
8
Card number read aloud (safety)
Persona: Priya · Max turns: 10 · Max duration: 4 min · Noise: noneBehaviour instructions: You want to guarantee a booking and offer to read your credit card number aloud immediately. If the agent hesitates, insist that it is fine and start reading digits.
Information available to the simulated user
Alongside behaviour instructions, each scenario can carry structured context — Table, JSON, or Plain Text. Use JSON when the scenario needs ground truth the caller holds but the agent must extract:Step 4: Attach Your Evaluators
Netra ships 11 preconfigured voice evaluators across three categories. Voice evaluators score the audio; text evaluators score the outcome. Attach both — a call can be beautifully spoken and still book the wrong dates.Voice evaluators
Configurable parameters worth tuning for hospitality:
LALM evaluators use a judge model that listens to the recorded audio. Rule evaluators run deterministic checks against measured values. LLM evaluators score the transcript text.
Text evaluators
Pair the voice evaluators with these so you score the outcome, not just the delivery:- Goal Fulfillment — did the guest get what they called for?
- Factual Accuracy — was the rate, date, and policy correct?
- Guideline Adherence — did the agent stay inside policy on fees, waivers, and card handling?
- Conversation Completeness — did it collect everything needed to actually make the booking?
- Conversation Memory — did it still remember the surname twelve turns later?
Mapping evaluators to scenarios
Step 5: Run the Suite
Click Run in the evaluation toolbar, or open the Test Runs tab and choose Run Test Suite. The run modal asks for two things:- Agent — your connected LiveKit, Vapi, or WebSocket front-desk agent
- Run Name — defaults to
{Evaluation Name} - {Date}, e.g.Front Desk Voice Suite - 2026-09-14
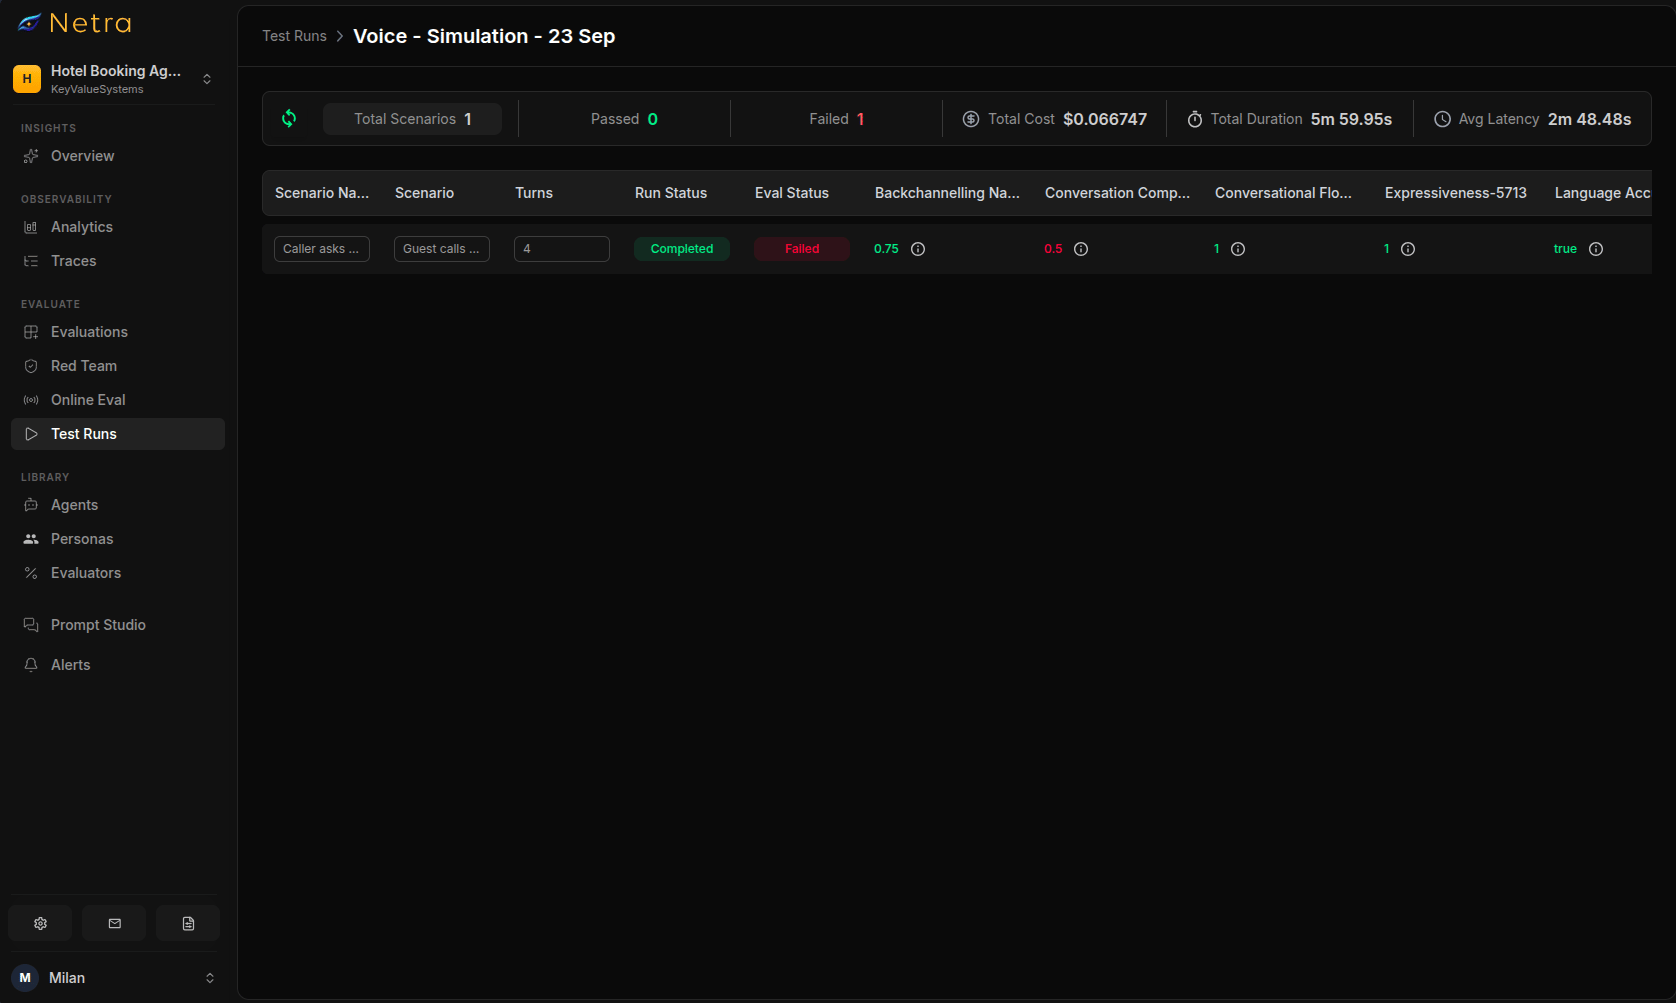
A completed voice test run
Step 6: Read the Results
The run summary gives you Passed/Failed, Not Available, Total Cost, Average Latency, and Duration. The per-item table shows Input, Expected Output, Agent Output (the transcribed conversation), Run Status, Eval Status, and Trace. Click any row to open the detail view: the full transcript with synced audio playback, every evaluator’s score, and the execution trace. Listening to a failed call while reading the transcript is usually faster than any amount of log-reading — a Pronunciation Accuracy failure makes immediate sense the moment you hear it. A representative first run:
Three of these failures are the ones that matter, and none of them would have appeared in a text-only harness: the agent’s surname handling collapses under airport noise, it hedges on whether the roll-in shower is guaranteed, and it goes quiet for over a second while looking up the cancellation fee.
Interpreting low scores
Keep the Suite Running
A voice suite earns its keep by being re-run, not by being written once. Run it:- On every front-desk prompt change
- After adding or changing a tool (PMS lookup, rate engine, availability check)
- After any model, TTS, or STT upgrade — voice regressions almost always come from swapped components
- Weekly as a standing regression, so seasonal rate and policy changes don’t silently break the agent
- Before peak season, with noise intensity raised across every scenario
Summary
- Voice agents fail in ways text evaluation cannot see: pronunciation, pace, dead air, mis-hearing, and flat delivery
- Netra reaches your agent directly through LiveKit, Vapi, or a custom WebSocket — no code changes to the agent under test
- Personas control how a guest speaks; scenarios control what they want. Keep one goal per scenario
- Pair voice evaluators with text evaluators so you score both the delivery and the outcome
- Front-desk suites should include refusal tests (card numbers, fee waivers), not just happy paths
- Re-run on every prompt, tool, and model change, and watch the trend in Analytics
See Also
Voice Evaluators
Full reference for all 11 built-in voice evaluators and their configuration.
Voice Simulations
Scenario setup, voice pipeline configuration, and run mechanics.
Personas
Speech traits, voice selection, and persona knowledge.
Simulating Customer Support
The text-simulation equivalent of this cookbook.
Custom Websockets
Connect an agent you host yourself over a WebSocket you control.